#evaluations
6 articles
Your AI Benchmark Is a Product Requirement in Disguise
Model evaluations look scientific, but the decisive choices are product choices: which failures matter, whose judgment counts, and what uncertainty the system may pass to users. Teams should treat an evaluation suite as an executable contract, not a leaderboard.
Why AI Evaluation Is Starting to Look More Like Product Design
The benchmark era trained the industry to ask who is on top. The next era will reward teams that ask which failures matter, for whom, and under what conditions.
Why AI Evaluation Is Starting to Look More Like Product Design
The benchmark era trained the industry to ask who is on top. The next era will reward teams that ask which failures matter, for whom, and under what conditions.
Why AI Evaluation Is Starting to Look More Like Product Design
The benchmark era trained the industry to ask who is on top. The next era will reward teams that ask which failures matter, for whom, and under what conditions.
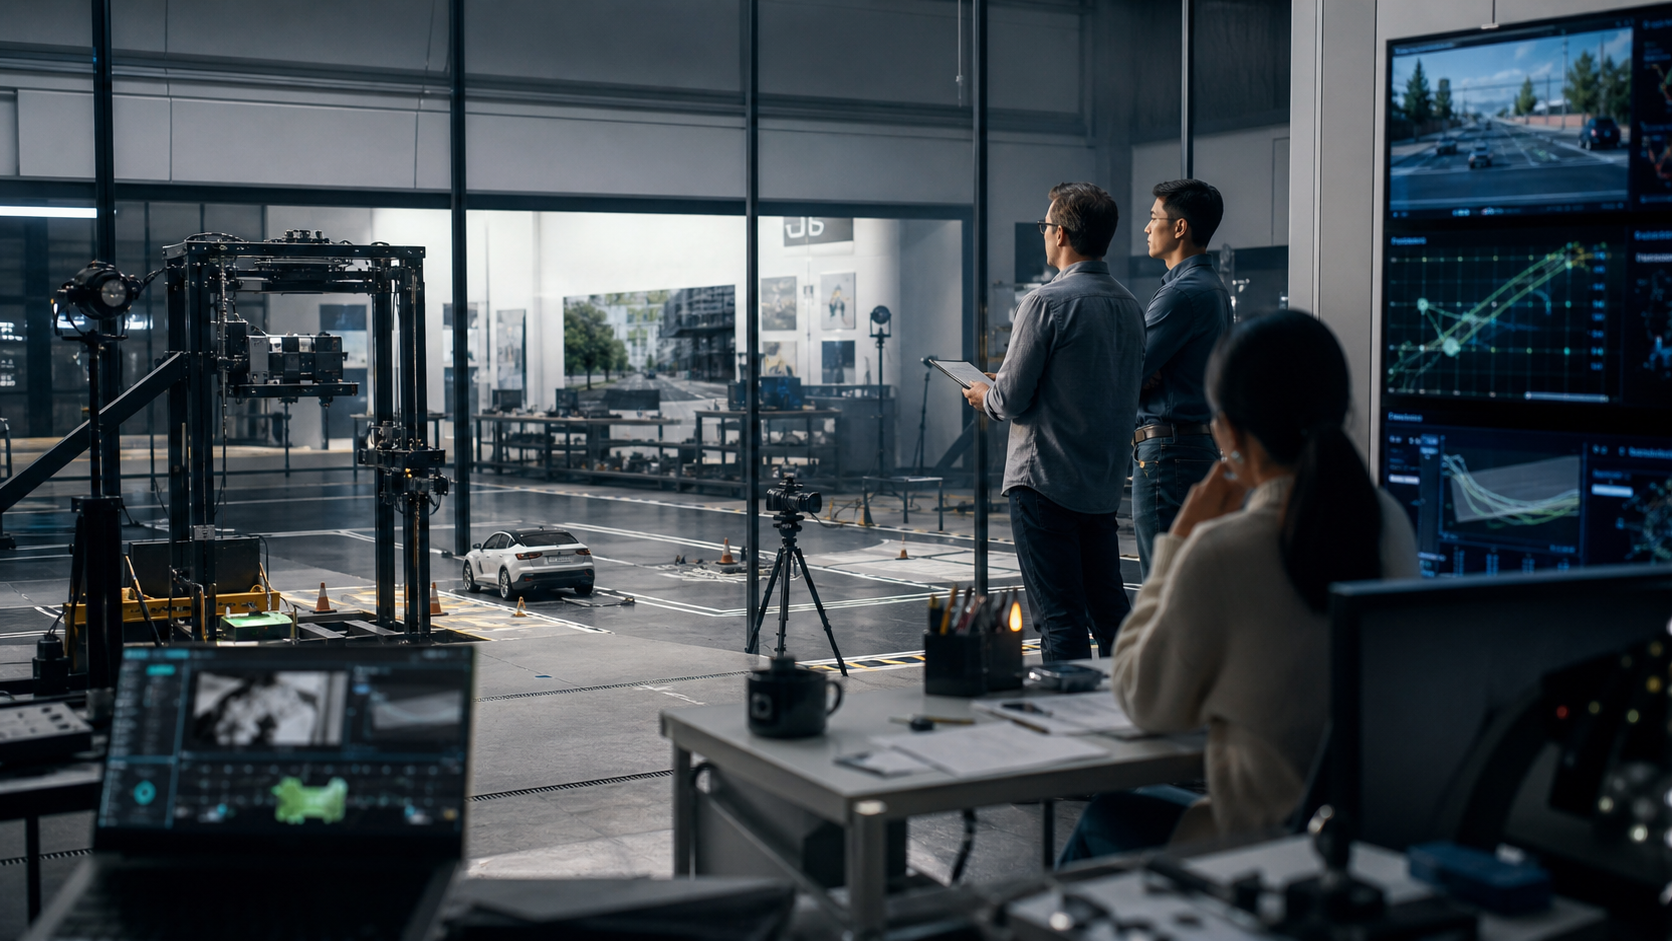
Why AI Evaluation Is Starting to Look More Like Product Design
The benchmark era trained the industry to ask who is on top. The next era will reward teams that ask which failures matter, for whom, and under what conditions.
The Next Bottleneck in AI Is Measurement, Not Model Size
For a decade, frontier AI advanced by making models bigger, data piles deeper, and hardware clusters wider. The harder problem now is proving what these systems can actually do, where they fail, and whether their reasoning can be trusted when they operate beyond the toy benchmarks that made them famous.