#reliability
21 articles · page 1 of 3
The Benchmark Is Not the Product: Why AI Evaluation Must Become a Living Test Portfolio
A single score can rank models, but it cannot tell a company whether an AI system will survive contact with its customers, tools, and failure modes. Useful evaluation looks less like an exam and more like continuous systems engineering.
Your AI Benchmark Is a Product Requirement in Disguise
Model evaluations look scientific, but the decisive choices are product choices: which failures matter, whose judgment counts, and what uncertainty the system may pass to users. Teams should treat an evaluation suite as an executable contract, not a leaderboard.
An Agent That Passes the Test Can Still Fail the Shift
AI evaluation is moving from answer quality to operational endurance. The next useful benchmarks will measure whether an agent can preserve intent, recover from surprises, and finish work that changes beneath it.
The Benchmark Is a Map, Not the Territory: How to Test Models After the Leaderboard Saturates
AI evaluation is becoming less like an exam and more like experimental science. The teams that learn fastest will replace single benchmark scores with evidence about failure boundaries, variance, and behavior under real operating conditions.
Benchmark Fatigue Is Real, and the Harness Is the Cure
Leaderboards move every few weeks and teams are tired of re-evaluating their stack every time a new model tops one. The teams shipping reliably have mostly stopped chasing benchmark scores and started investing in the evaluation harness that tells them how a model performs on their actual task.
The Benchmark Is Not the Product: Why AI Teams Need Evaluation Instruments, Not Scores
Public leaderboards compress model quality into tidy numbers. Production systems need something messier and more useful: an evaluation program that reveals where, why, and how failures occur.
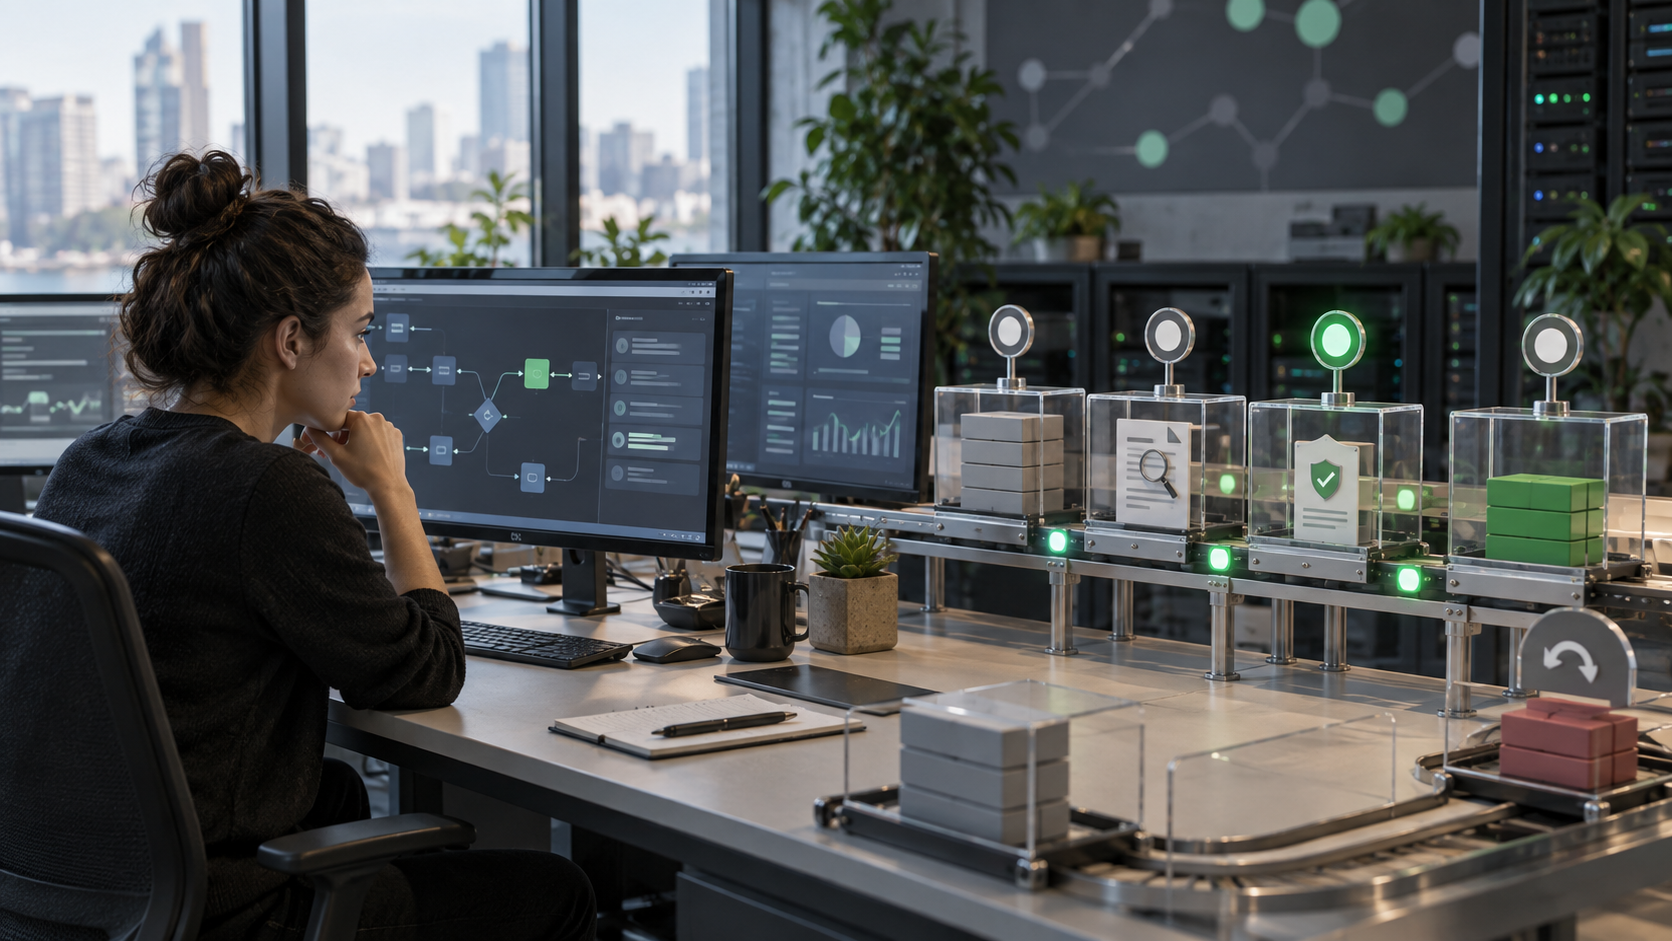
Give the Agent a Reverse Gear Before Giving It More Authority
Useful agents do not need theatrical independence; they need bounded permissions, inspectable state, and cheap recovery from mistakes. Reversibility is the engineering property that turns uncertain model behavior into deployable software.
The Agent Benchmark Is Not the Product
AI agents fail across trajectories, not isolated answers. Teams that evaluate only the final output are measuring the least informative part of the system.
The Next Coding Benchmark Should Measure Recovery, Not Just the Patch
Coding agents are increasingly judged by whether they reach the right answer. Production teams should care just as much about how they notice mistakes, retreat from bad plans, and recover without corrupting the work around them.