#coding-agents
16 articles · page 2 of 2
The Coding-Agent Benchmark Is Becoming the Product Spec
Coding benchmarks once offered a clean scoreboard. As agents move into real repositories, the harder question is whether our tests measure useful engineering—or merely train products to perform the test.
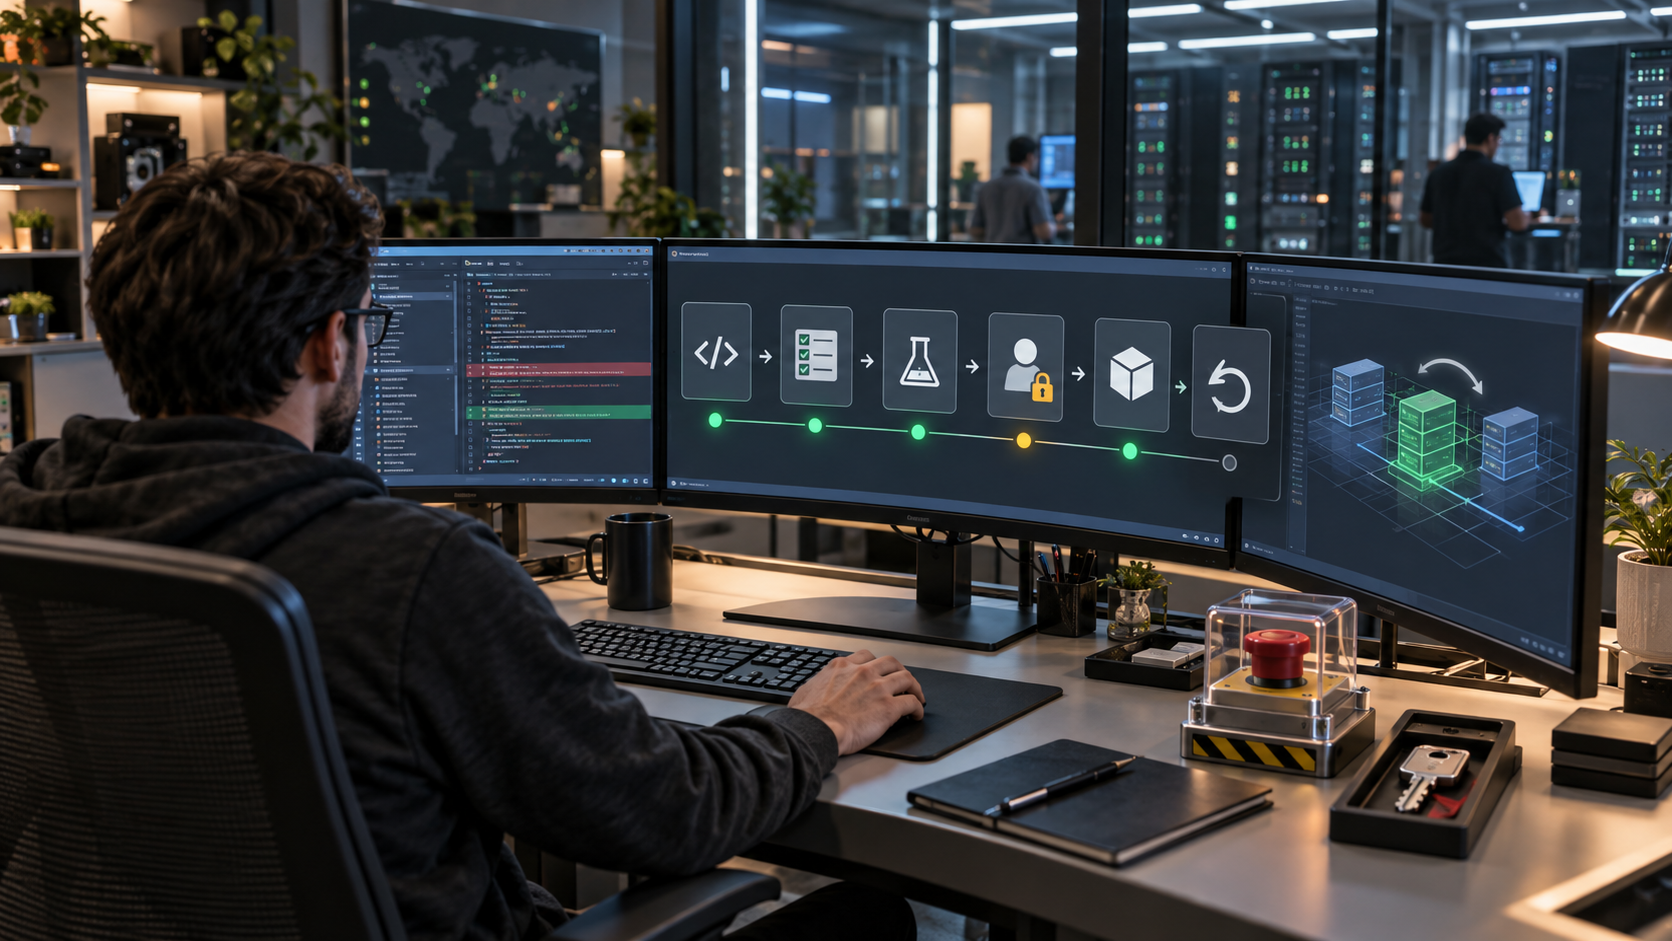
Stop Designing Coding Agents as Chatbots With Shell Access
A production coding agent is not primarily a conversational interface. It is a controlled operator whose real product surface consists of permissions, evidence, recovery, and handoff.
The Benchmark Passed. The Software Still Broke.
Coding-agent evaluations are getting harder, but a larger test suite is not the same as a better measurement. The next useful benchmark will judge recovery, restraint, and maintainability—not merely whether a patch turns the checks green.
Coding Agents Need Change Budgets, Not Blank Checks
The central risk of AI-assisted software development is not that agents write bad code; teams already know how to reject bad code. It is that they can create more plausible change than an organization can responsibly understand.
Give Coding Agents a Budget of Authority, Not a Longer Prompt
The safest useful coding agent is not the one with the most elaborate instructions. It is the one whose permissions, evidence requirements and rollback paths make good behavior easier than improvisation.
The Benchmark Is Part of the Model Now
Public leaderboards increasingly measure how well an AI system has adapted to a test ecosystem, not merely whether it can solve the underlying task. Serious evaluation must become a living engineering practice rather than a quarterly scorecard.
The Best Coding Agent Leaves a Better Audit Trail Than Its Author
AI-generated code is not the hardest governance problem. The harder problem is reconstructing why a change was made, what evidence supported it, and which assumptions survived review.