#agents
40 articles · page 1 of 5
The Benchmark Is Becoming Part of the Model
Static leaderboards once helped the field compare models. Now contamination, optimization pressure, and agentic behavior are turning evaluation into a continuously operated research system rather than a fixed exam.
The Best AI Workflow Begins Where Automation Stops
Most enterprise AI projects optimize the happy path and treat human review as an embarrassing fallback. Durable systems do the opposite: they design the exception lane first, then automate only what can enter and leave it safely.
An Agent That Passes the Test Can Still Fail the Shift
AI evaluation is moving from answer quality to operational endurance. The next useful benchmarks will measure whether an agent can preserve intent, recover from surprises, and finish work that changes beneath it.
Your AI Product Needs an Exception Desk Before It Needs Another Agent
Automation demos celebrate the happy path, while durable systems are defined by what happens when evidence conflicts and tools fail. The exception queue is not operational debris; it is the product’s learning surface.
A Reasoning Benchmark Is a User Interface, Not a Ruler
Reasoning models do not merely answer tests; they interact with them. Evaluation must therefore measure how systems spend effort, use tools, recover from errors, and behave under changing constraints.
Give AI Agents Smaller Rooms and Better Doors
The safest useful agent is not the one surrounded by the most warnings. It is the one whose environment makes valid actions easy, consequential actions explicit, and mistakes reversible.
Don’t Give the Agent a Job Title: Give It a Queue, a Budget, and an Escalation Rule
Anthropomorphic “digital worker” language leads teams toward brittle automation. Reliable applied AI starts by redesigning the flow of work around bounded tasks, observable state, and explicit authority.
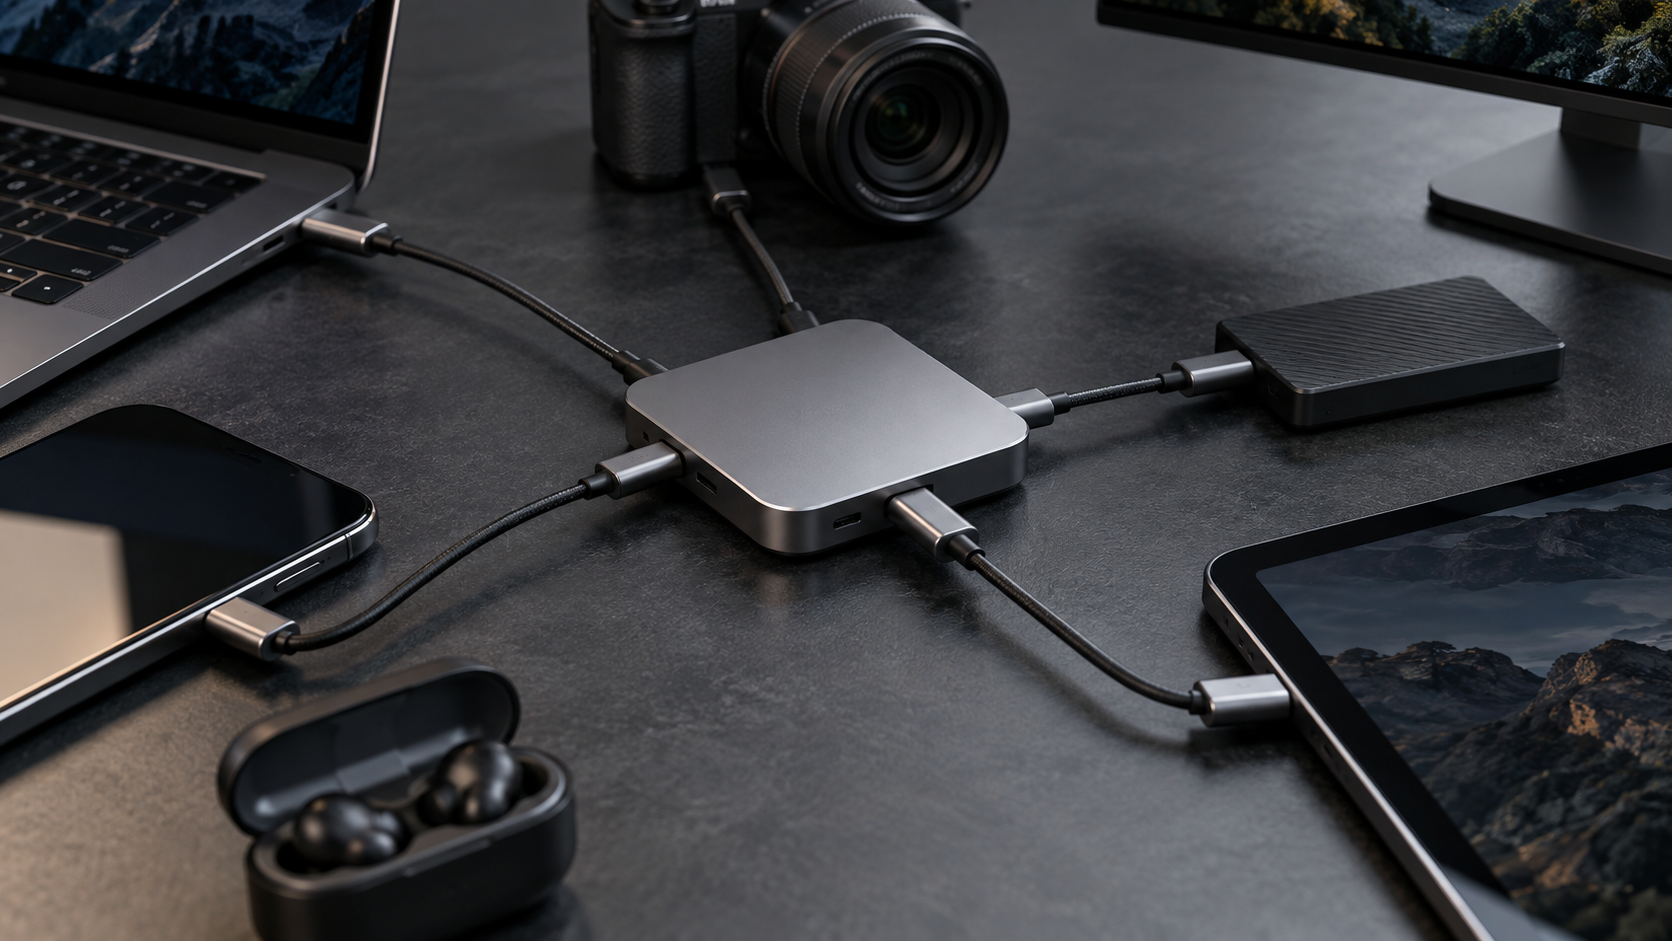
The Model Context Protocol Is Turning Into AI's USB-C Moment
For two years every AI agent needed a bespoke integration to touch your files, your database, or your ticketing system. MCP is quietly ending that, and the fact that it comes from a model vendor rather than a standards body is exactly why it is working.
The Benchmark Should Expire Before the Model Does
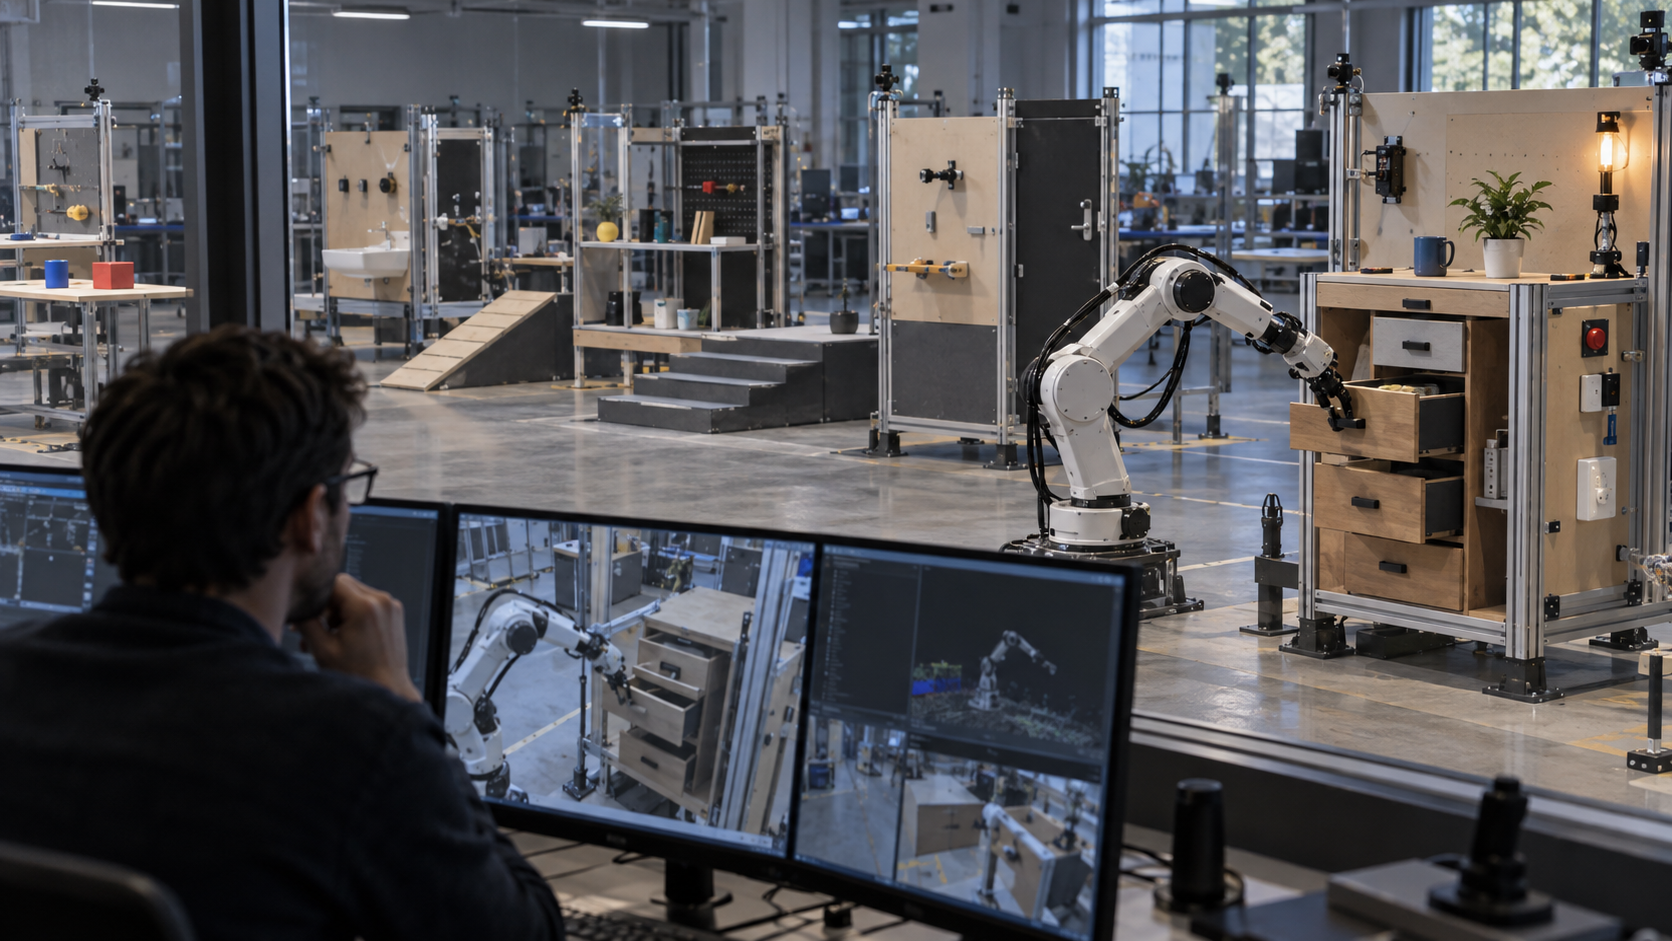
Static leaderboards turn yesterday’s hard problems into today’s training material. Serious AI evaluation now needs rotating tests, hidden environments, and an explicit shelf life.