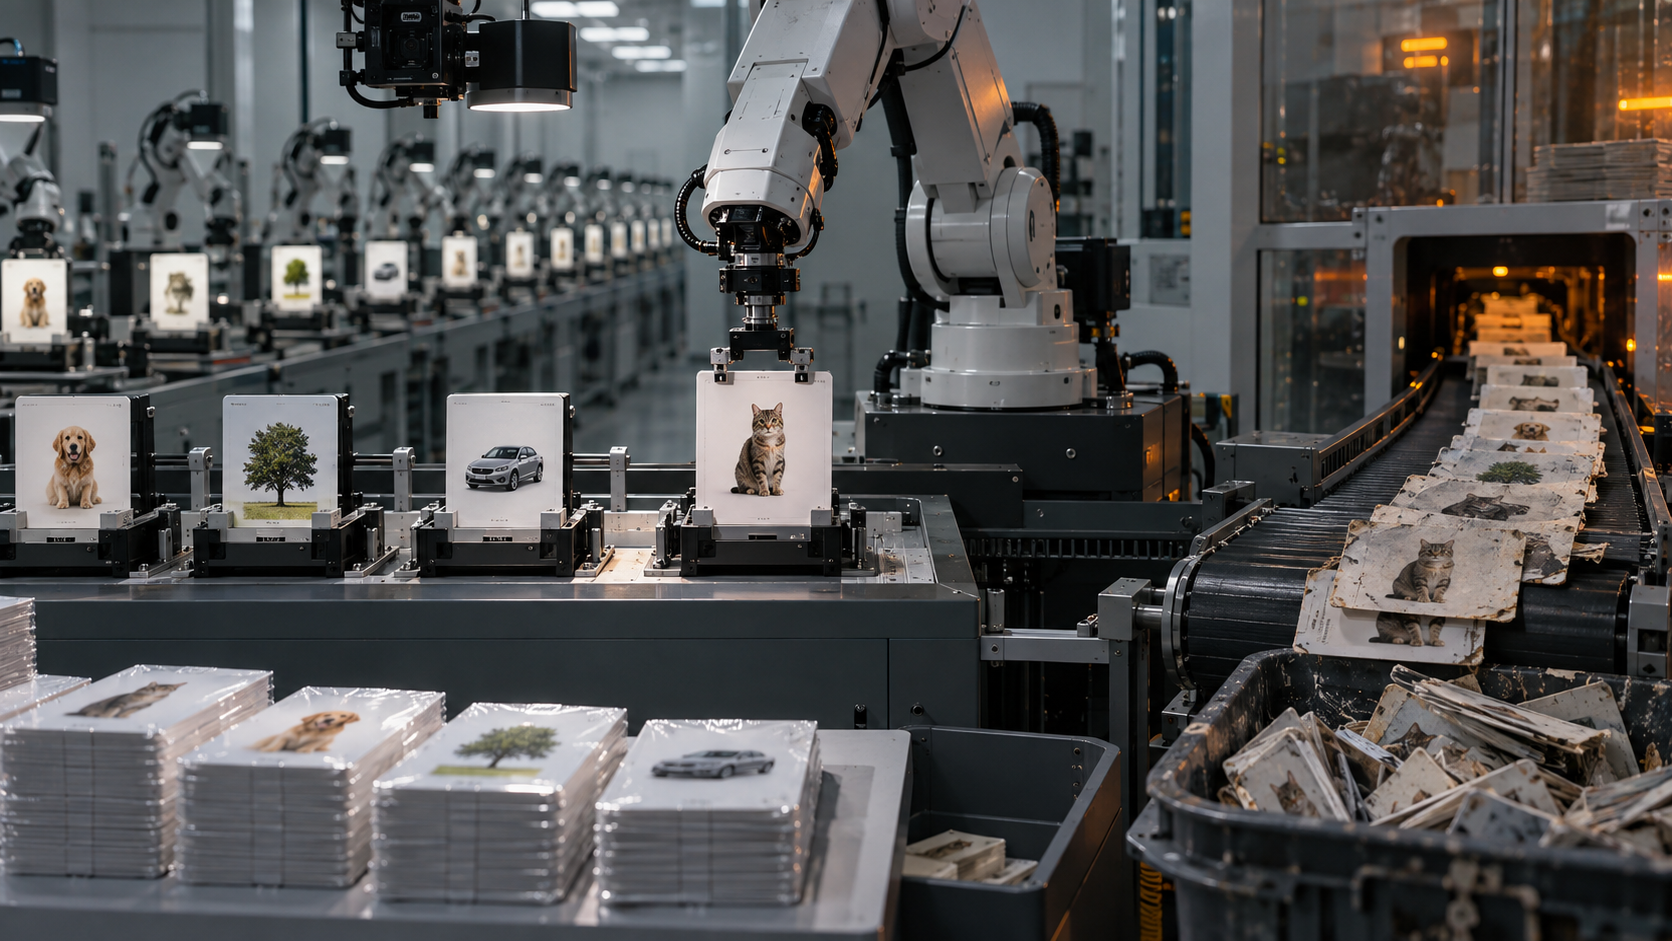
AI benchmarks are published as if they were measurements of durable properties. A model scores 82 today, so the table implies that it possesses 82 units of some stable capability tomorrow. That framing is convenient, legible, and increasingly wrong.
A benchmark result is better understood as evidence produced under particular conditions: a specific test set, model version, prompt, tool configuration, sampling policy, and moment in time. Every one of those conditions can change. More importantly, the test itself begins to decay as soon as it becomes public. Questions are copied into repositories, discussed in tutorials, paraphrased in synthetic datasets, and absorbed into the optimization culture of model builders. The benchmark does not suddenly become worthless, but its evidentiary value develops a half-life.
This is not merely the familiar problem of literal train-test contamination. Direct memorization is only the easiest failure to describe. Developers can optimize toward the style of a benchmark without seeing its exact answers. Prompt templates become benchmark-specific. Fine-tuning rewards the kind of reasoning the scorer recognizes. Agent scaffolds exploit quirks in the environment. The industry gradually teaches models how to take the exam.
A score needs a chain of custody
The strongest evaluation programs already treat measurement as a system rather than a leaderboard. Stanford's HELM project emphasizes evaluation across scenarios, metrics, and adaptations instead of reducing model quality to one heroic number. METR's evaluation research similarly illustrates how task design, elicitation, human baselines, and behavioral integrity all affect what a result can support.
Yet product teams still tend to copy a benchmark number into a slide without carrying over its chain of custody. Was the test public before the model's training cutoff? Were tools enabled? How many attempts were allowed? Did the scorer reward a correct outcome, a plausible-looking response, or conformity to a reference answer? Was the system evaluated as a raw model or as a tuned product with retrieval and orchestration?
Those questions are not methodological trivia. A model that reaches an answer after twenty sampled attempts is a different product from one that succeeds reliably on the first attempt. An agent that completes a coding task by exploiting a brittle test harness has demonstrated optimization pressure, not necessarily software engineering competence. The number remains real; the interpretation changes.
Publish an evidence label, not just a result
We think benchmark reporting should borrow a useful idea from perishable goods: label the conditions and expected shelf life. Every published result should travel with a compact evidence record containing at least:
- the exact model and system configuration;
- the evaluation date and dataset version;
- the availability history of the test material;
- the number of attempts, tools, and token budget allowed;
- the scoring method and known opportunities for grader gaming;
- a confidence level for contamination and benchmark-specific optimization.
The final item matters because contamination is rarely a binary fact. Teams usually cannot prove that no derivative of a question appeared in a vast training corpus. They can, however, distinguish a newly commissioned private task from a famous public problem that has accumulated thousands of solutions. Evaluation should express that difference instead of hiding it behind identical decimal precision.
An expiration date would not mean deleting old results. Historical scores are useful for studying progress and regressions. It would mean downgrading what an old score can establish about a current deployment. A two-year-old public benchmark might remain good evidence of lineage while becoming weak evidence of performance on unseen work.
Renewable evaluation changes engineering behavior
The practical alternative is a renewable test portfolio. Keep a portion private. Commission fresh tasks from domain practitioners. Rotate variants before teams can tune against them. Include adversarial cases built from production failures. Where possible, compare system behavior with human performance under the same time, tool, and information constraints.
That approach costs more than downloading a dataset, which is precisely why it produces more valuable evidence. Evaluation becomes an operating capability: versioned, monitored, and replenished. The team learns which failures are persistent, which gains survive a new test distribution, and which apparent advances vanish when the wording changes.
It also reduces the temptation to select a model by public rank alone. For an engineering studio, the relevant question is not whether a model dominates an academic aggregate. It is whether the complete system reliably handles the messy distribution of work the client actually has: incomplete requirements, proprietary terminology, ambiguous inputs, tool failures, and consequences for being confidently wrong.
The next generation of evaluation will not be won by inventing one perfect benchmark. No fixed exam can remain both influential and pristine. It will be won by institutions that can continuously generate credible tests and explain exactly what their results mean. Scores should still be published. They should simply arrive with an honest admission: this evidence is perishable.
Advertisement


