Tools & Products
4 articles
Open-Weight Models Just Became a Procurement Decision, Not a Research One
Running your own model used to be a research project with an uncertain payoff. With serious open-weight releases now clustering close to proprietary frontier performance on many tasks, the conversation inside regulated companies has shifted from "can we" to "should we," and that is a very different, much faster conversation.
Benchmark Fatigue Is Real, and the Harness Is the Cure
Leaderboards move every few weeks and teams are tired of re-evaluating their stack every time a new model tops one. The teams shipping reliably have mostly stopped chasing benchmark scores and started investing in the evaluation harness that tells them how a model performs on their actual task.
The Terminal Is Quietly Becoming the Best AI Product Surface
Chat windows were the first home for AI assistants and IDE sidebars were the second. The place coding agents are actually earning their keep now is older than both: the command line, where an agent can read a whole repository, run tests, and show its work in a format engineers already trust.
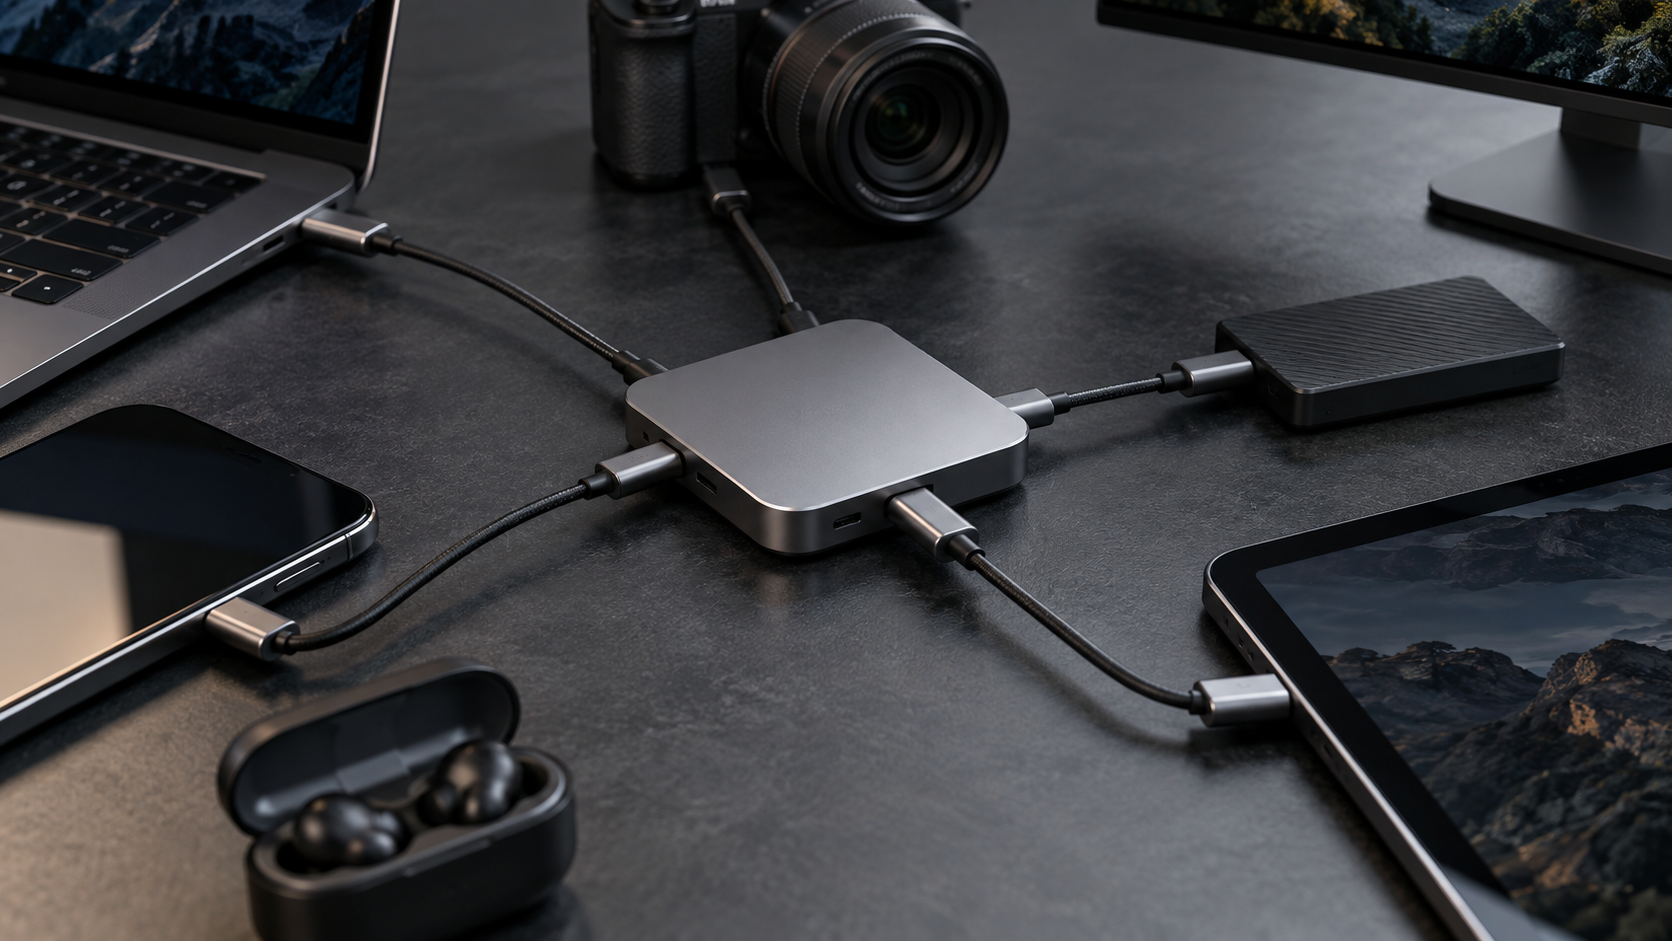
The Model Context Protocol Is Turning Into AI's USB-C Moment
For two years every AI agent needed a bespoke integration to touch your files, your database, or your ticketing system. MCP is quietly ending that, and the fact that it comes from a model vendor rather than a standards body is exactly why it is working.