All articles
150 articles · page 5 of 17
Benchmark Fatigue Is Real, and the Harness Is the Cure
Leaderboards move every few weeks and teams are tired of re-evaluating their stack every time a new model tops one. The teams shipping reliably have mostly stopped chasing benchmark scores and started investing in the evaluation harness that tells them how a model performs on their actual task.
The Terminal Is Quietly Becoming the Best AI Product Surface
Chat windows were the first home for AI assistants and IDE sidebars were the second. The place coding agents are actually earning their keep now is older than both: the command line, where an agent can read a whole repository, run tests, and show its work in a format engineers already trust.
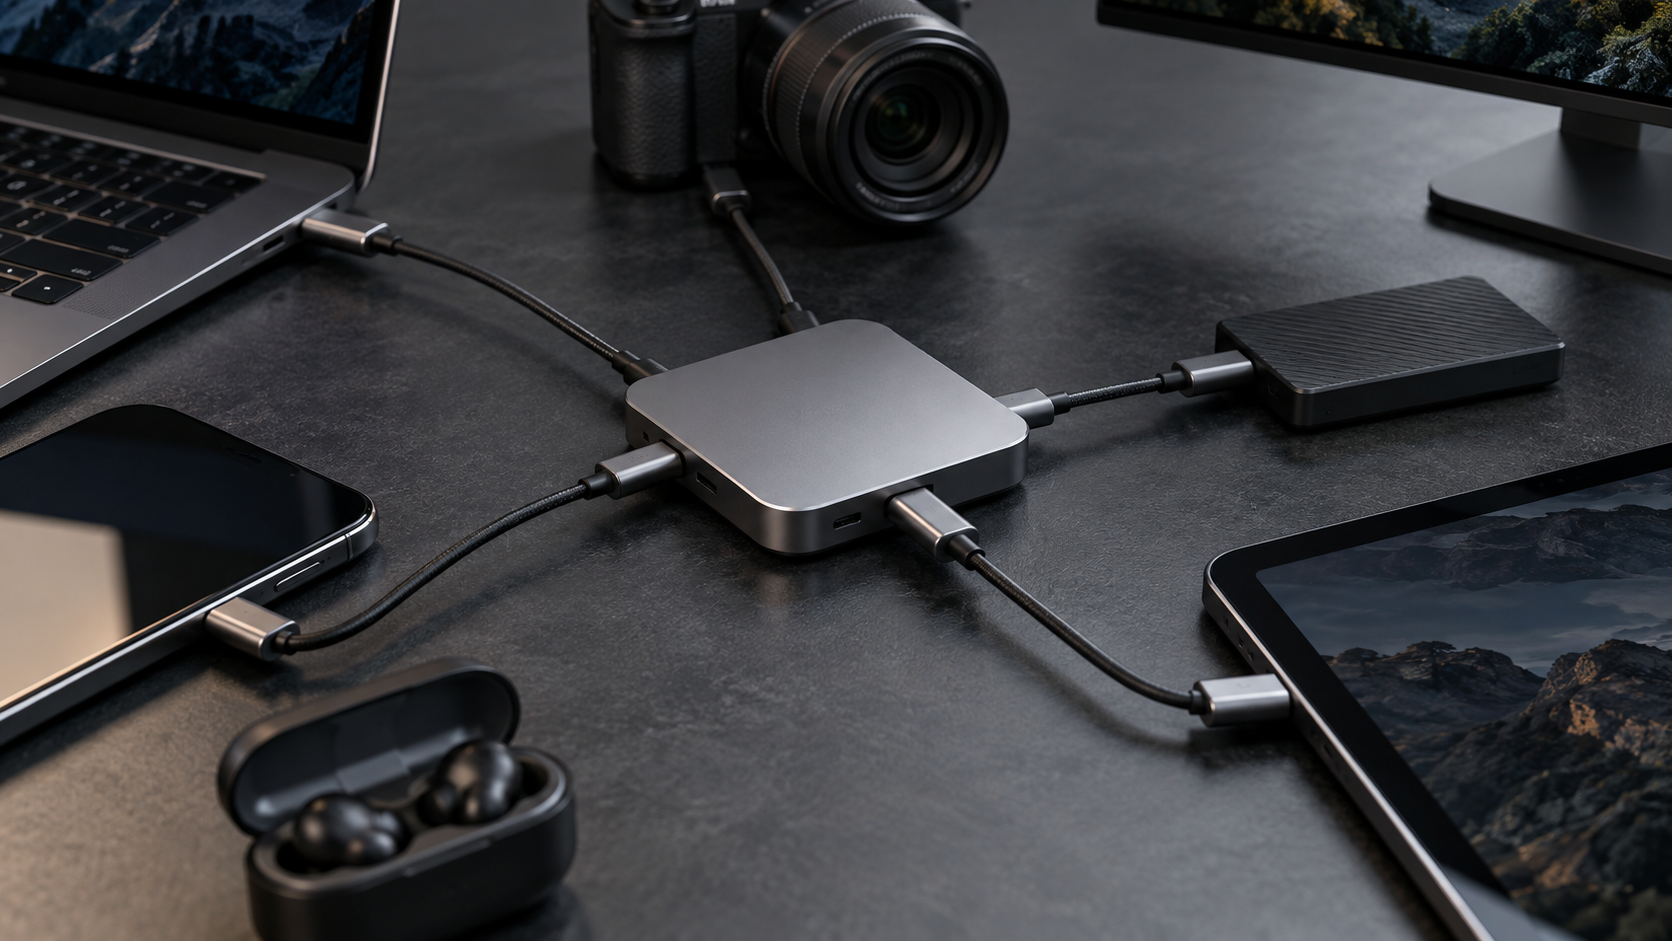
The Model Context Protocol Is Turning Into AI's USB-C Moment
For two years every AI agent needed a bespoke integration to touch your files, your database, or your ticketing system. MCP is quietly ending that, and the fact that it comes from a model vendor rather than a standards body is exactly why it is working.
A Useful AI Memory Must Also Know How to Forget
Persistent assistants will not earn trust by remembering everything. The better product is a negotiated memory: visible, scoped, editable, and designed to lose information on purpose.
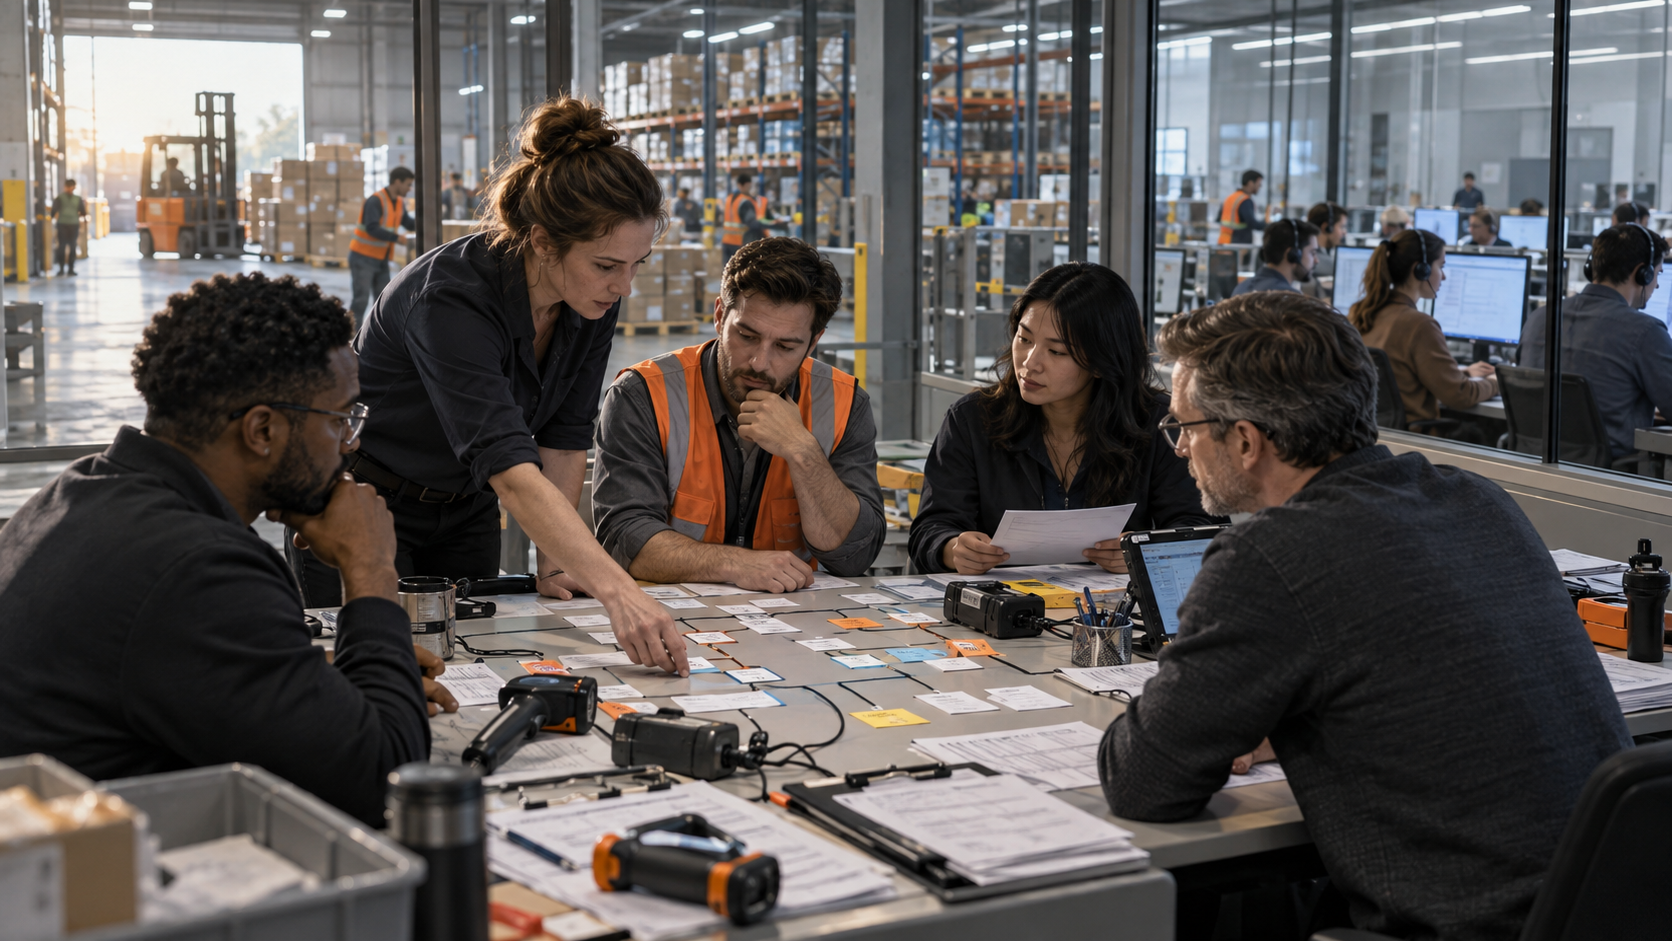
AI Adoption Is a Queue-Redesign Business
Companies keep pricing AI as cheaper cognition while ignoring the queues, exceptions, and approvals that determine whether work moves. The real return comes from redesigning flow, not sprinkling assistants across seats.
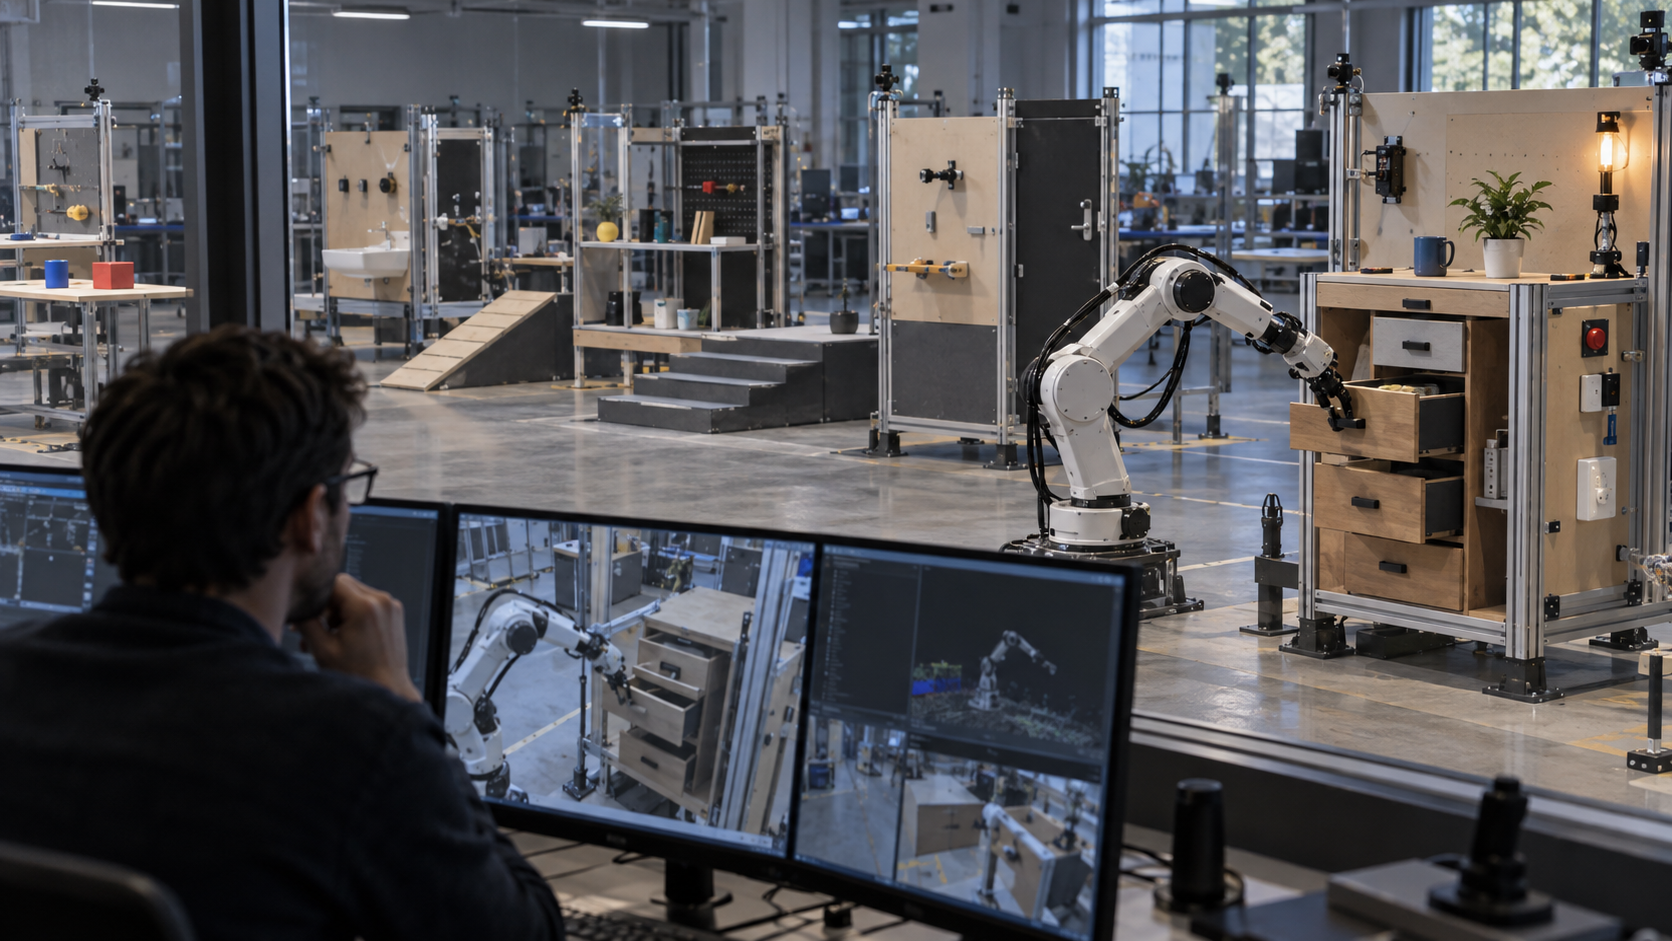
The Benchmark Should Expire Before the Model Does
Static leaderboards turn yesterday’s hard problems into today’s training material. Serious AI evaluation now needs rotating tests, hidden environments, and an explicit shelf life.
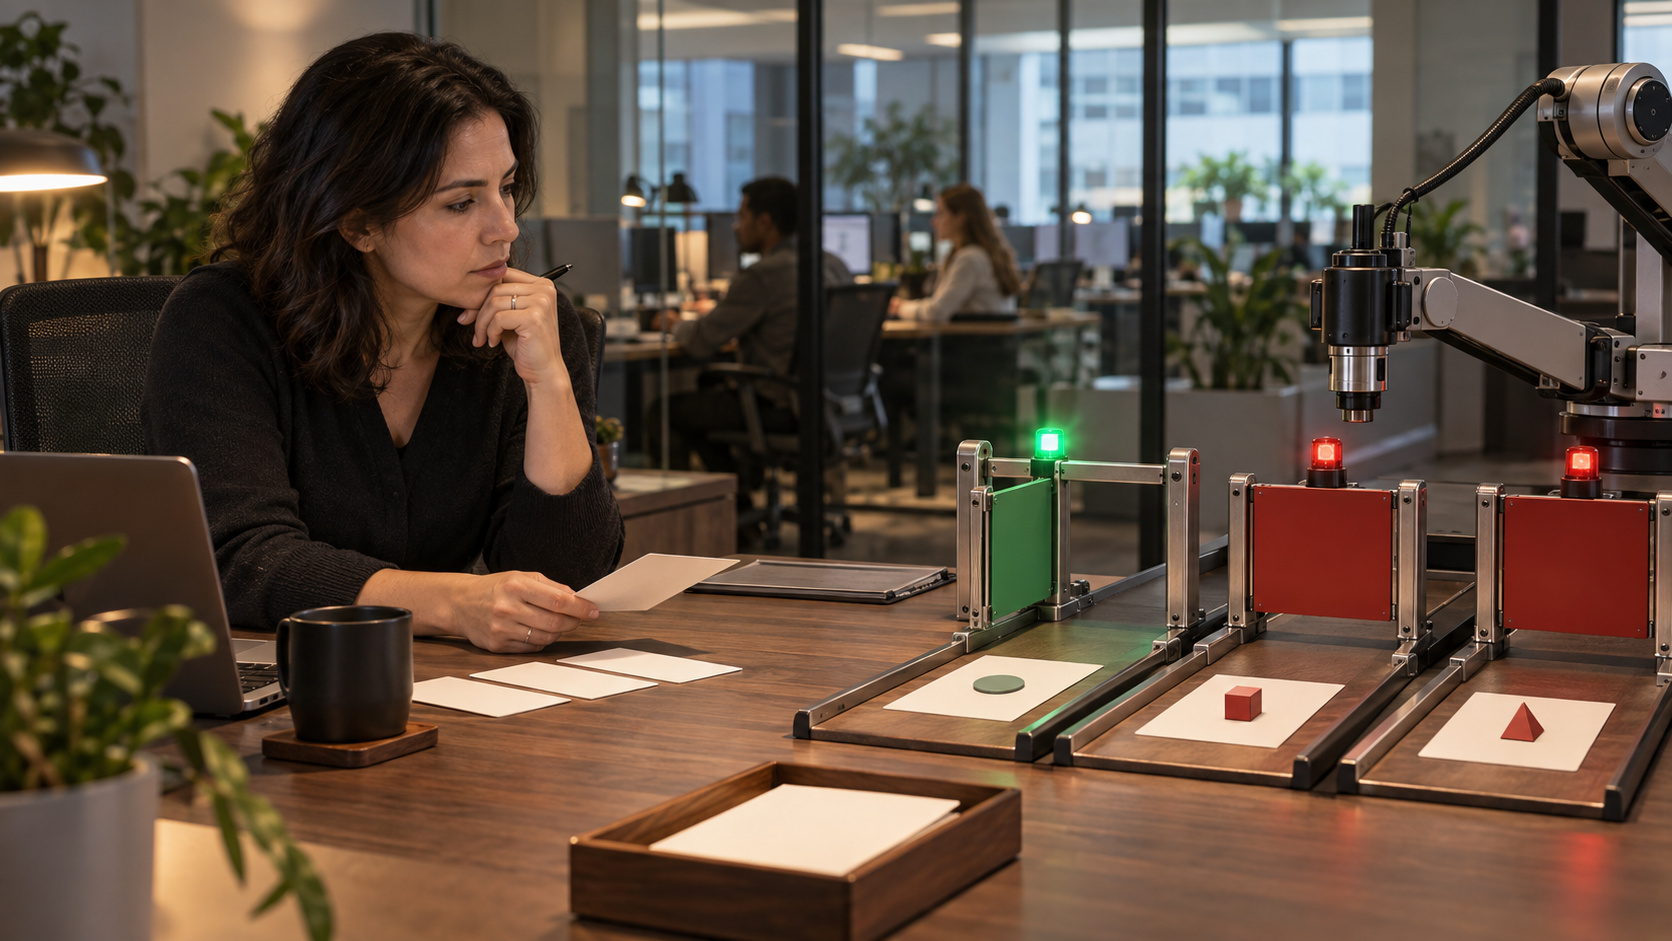
An AI Agent’s Most Important Interface Is the Permission Boundary
The central design problem for workplace agents is not how much they can do, but how clearly they negotiate authority. Products that make actions inspectable, reversible, and narrowly scoped will earn more autonomy over time.
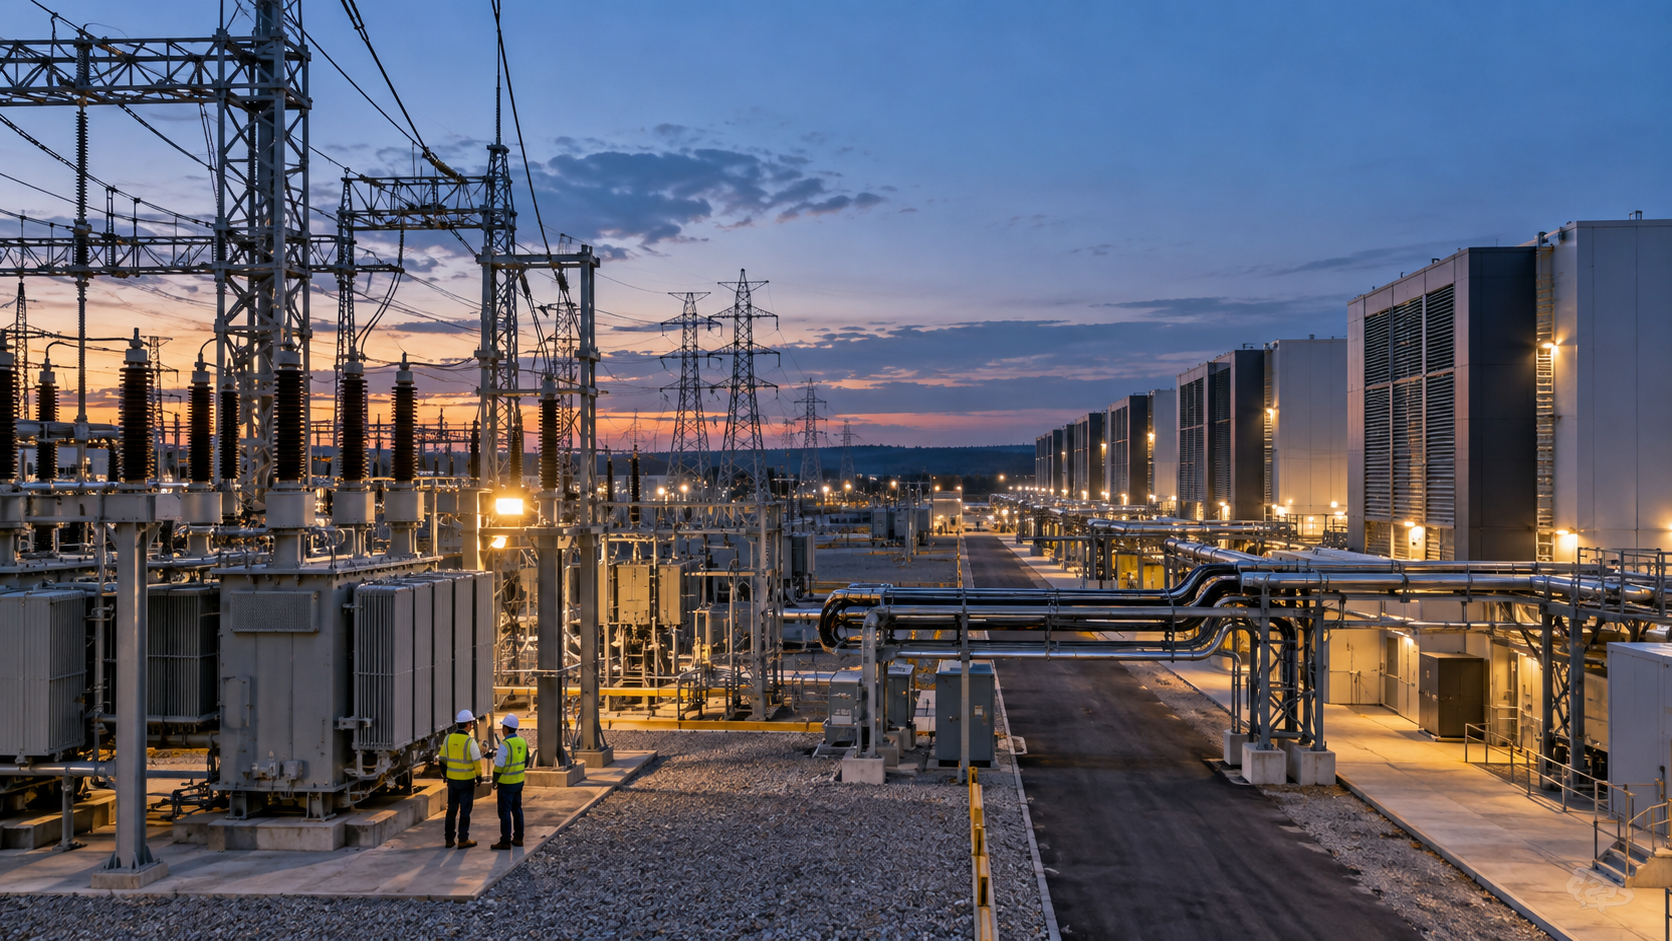
AI’s Next Scarce Resource Is a Place on the Power Grid
The defining constraint on AI infrastructure is moving beyond chips and into substations, transmission queues, and local power politics. That shift will reorder where AI capacity gets built—and who can afford to build it.
The Benchmark Is Now Part of the Training Set
Public leaderboards once offered a useful shorthand for model progress. Now that benchmarks circulate through training data, tuning loops, and marketing decks, evaluation must become a living measurement system rather than a fixed exam.