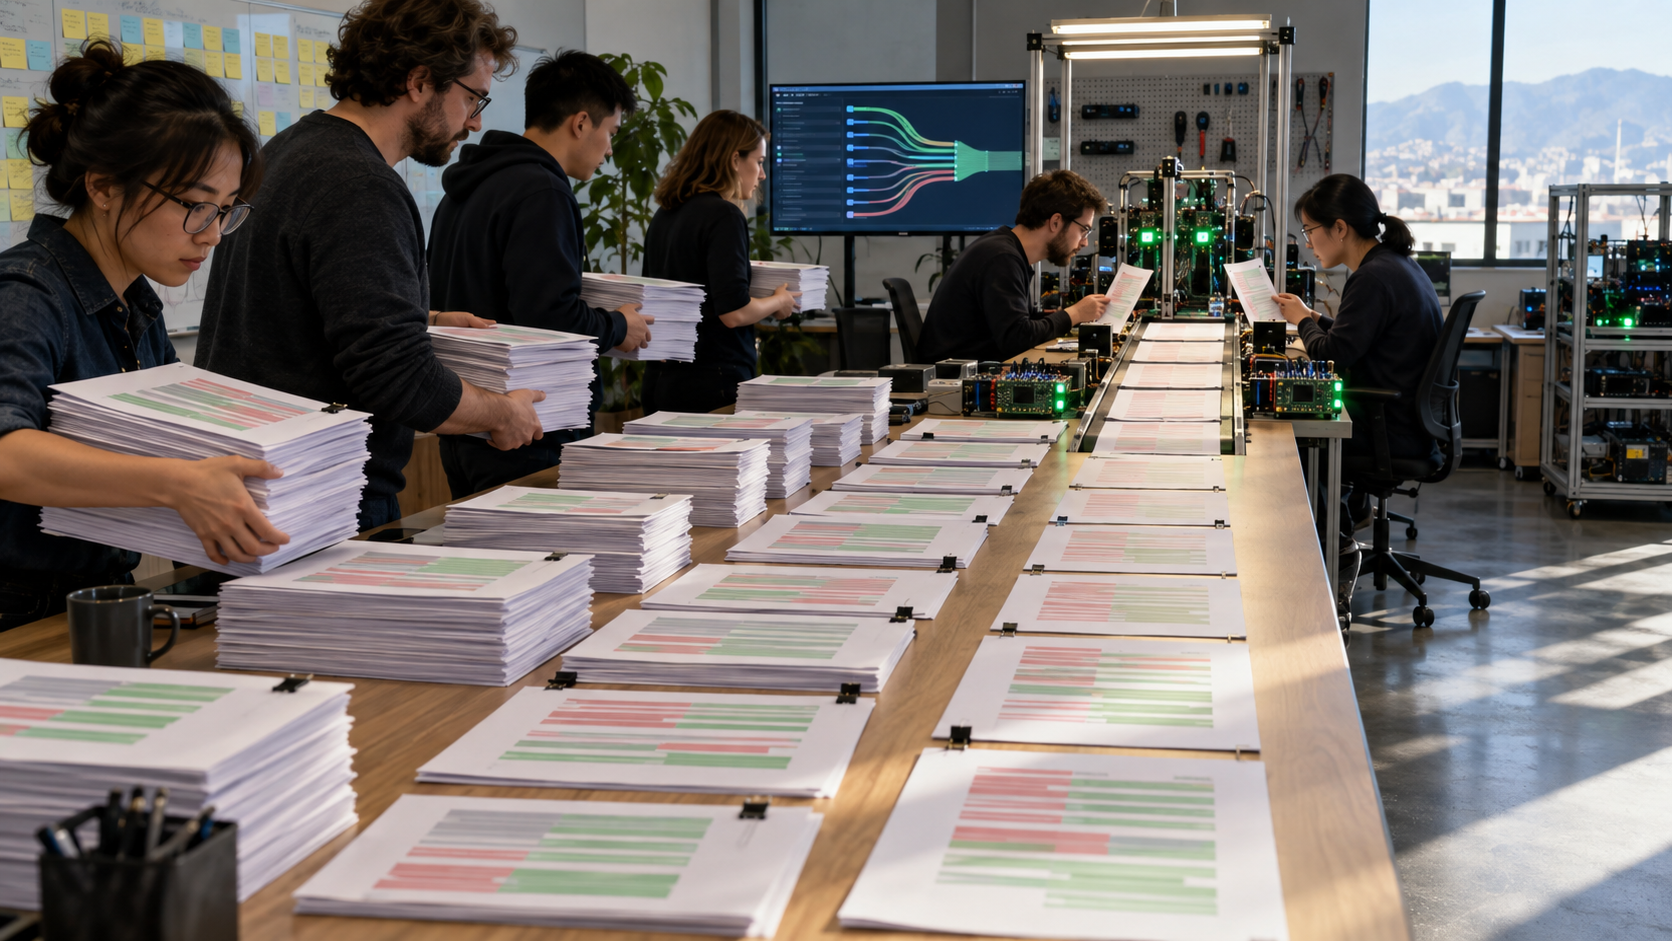
For decades, software organizations optimized the act of producing code. They hired for implementation speed, celebrated output, and treated review as a final quality gate. Coding agents disturb that arrangement because they make plausible changes cheap. The result is not a world without bottlenecks. It is a system in which the bottleneck moves from writing code to deciding what deserves to merge.
This shift is easy to miss during individual use. A developer asks an agent for a feature, watches files change, runs tests, and feels the acceleration. At team scale, those saved minutes reappear elsewhere. More pull requests arrive. Diffs grow. Generated tests restate the implementation instead of challenging it. Reviewers must reconstruct assumptions that were never written down because producing the patch felt effortless.
The scarce capability is no longer keystrokes. It is judgment backed by context.
Cheap patches create specification debt
Technical debt describes software that works now but imposes future cost. Coding agents create a related liability: specification debt. This is the gap between what a change appears to do and the reasoning required to know whether it is the right change.
When implementation is expensive, teams are forced to discuss scope before committing effort. When implementation becomes cheap, the temptation is to “just try it.” That is healthy for reversible experiments. It is dangerous when generated code crosses authorization boundaries, changes data models, or introduces behavior that cannot be inferred from local tests.
The original SWE-bench project helped move coding evaluation toward real repository issues rather than isolated programming questions. SWE-Bench Pro pushes further toward longer, more complex repository work. These benchmarks matter, but production teams face an additional challenge: the ticket itself is often incomplete, organizational knowledge is unevenly distributed, and “passes the tests” may still be the wrong outcome.
A generated patch should therefore arrive with a compact decision record. What behavior changed? Which requirement supports it? What assumptions were made? What evidence would falsify those assumptions? Which parts are mechanically verified, and which still depend on human judgment? The goal is not more prose. It is to transfer the reasoning burden from the reviewer’s imagination into an inspectable artifact.
Review throughput is a design problem
Teams commonly respond to an expanding review queue by asking reviewers to work faster or by adding another automated reviewer. Both can help, but neither addresses the shape of the queue. Review effort depends less on line count than on uncertainty, coupling, and consequence.
A small permissions change can deserve more scrutiny than a large generated fixture. Organizations should route changes accordingly. Low-risk, strongly verified updates may merge through narrow automated lanes. Changes touching identity, money, privacy, migrations, or public interfaces should require explicit evidence and ownership. This is not bureaucracy applied evenly; it is attention allocated according to blast radius.
The practical architecture resembles a control system:
- Define invariants before generation, including behavior that must not change.
- Give the agent the smallest permissions and scope that can complete the job.
- Require tests derived from the specification, not merely from the produced implementation.
- Record provenance for generated changes and the evidence used to accept them.
- Escalate ambiguous product decisions instead of encoding a convenient guess.
Anthropic’s account of effective agent design argues for simple, composable patterns and a deliberate distinction between fixed workflows and autonomous agents. That distinction is useful in software delivery. Most engineering work does not need maximal autonomy. A constrained workflow with checkpoints is often faster in practice because reviewers can understand where judgment entered the process.
Tests must become adversarial evidence
Generated code and generated tests can share the same misunderstanding. If an agent assumes that deactivated users retain access until a token expires, it may implement and test that assumption consistently. A green suite then proves internal agreement, not correctness.
Good verification needs independence. Acceptance tests should originate from product invariants, historical incidents, contracts, and observed production behavior. For sensitive changes, a separate process should attempt to break the patch without seeing the implementation rationale first. Static analysis, property-based testing, shadow traffic, staged rollouts, and rollback drills each provide a different kind of evidence. No single model critique substitutes for that diversity.
This also changes the senior engineer’s role. Expertise becomes more valuable, not less, because experts can state constraints, recognize unsafe shortcuts, and identify where apparently local changes touch a wider system. Their leverage shifts from personally producing every implementation to designing environments in which more implementation can be trusted.
Measure accepted change, not generated volume
Organizations will get the behavior they reward. Measuring lines generated, tasks attempted, or pull requests opened encourages a flood. Even measuring time-to-first-patch can be misleading if review and rework expand afterward.
A better metric is time to verified, deployed, and observed change. Pair it with review minutes, rollback frequency, escaped defects, and the percentage of agent work discarded before merge. Discarded work is not automatically failure—cheap exploration is valuable—but an unexplained rise indicates that generation has outrun specification.
The most effective AI-native engineering team will not be the one producing the most code. It will be the one that can absorb a high rate of proposed change without losing architectural coherence or exhausting its reviewers. That requires better queues, sharper invariants, and artifacts that make reasoning visible.
Coding has not become irrelevant. It has become abundant enough to expose the work that was always harder: choosing the right change, proving it behaves, and accepting responsibility for what enters the system.
Advertisement


