Teams building AI agents often measure progress by how long the system can operate without asking a person for help. That metric rewards visible autonomy: more tools, longer task chains, fewer interruptions. It also encourages the wrong architecture.
The central problem with an agent is not that it occasionally needs approval. The problem is that a plausible but mistaken action can alter the world: sending a message, merging code, changing a customer record, issuing a refund, or deleting a resource. As authority expands, accuracy alone is a weak safety strategy. Even an excellent model will encounter ambiguous instructions, unfamiliar states, and tools whose consequences it has misunderstood.
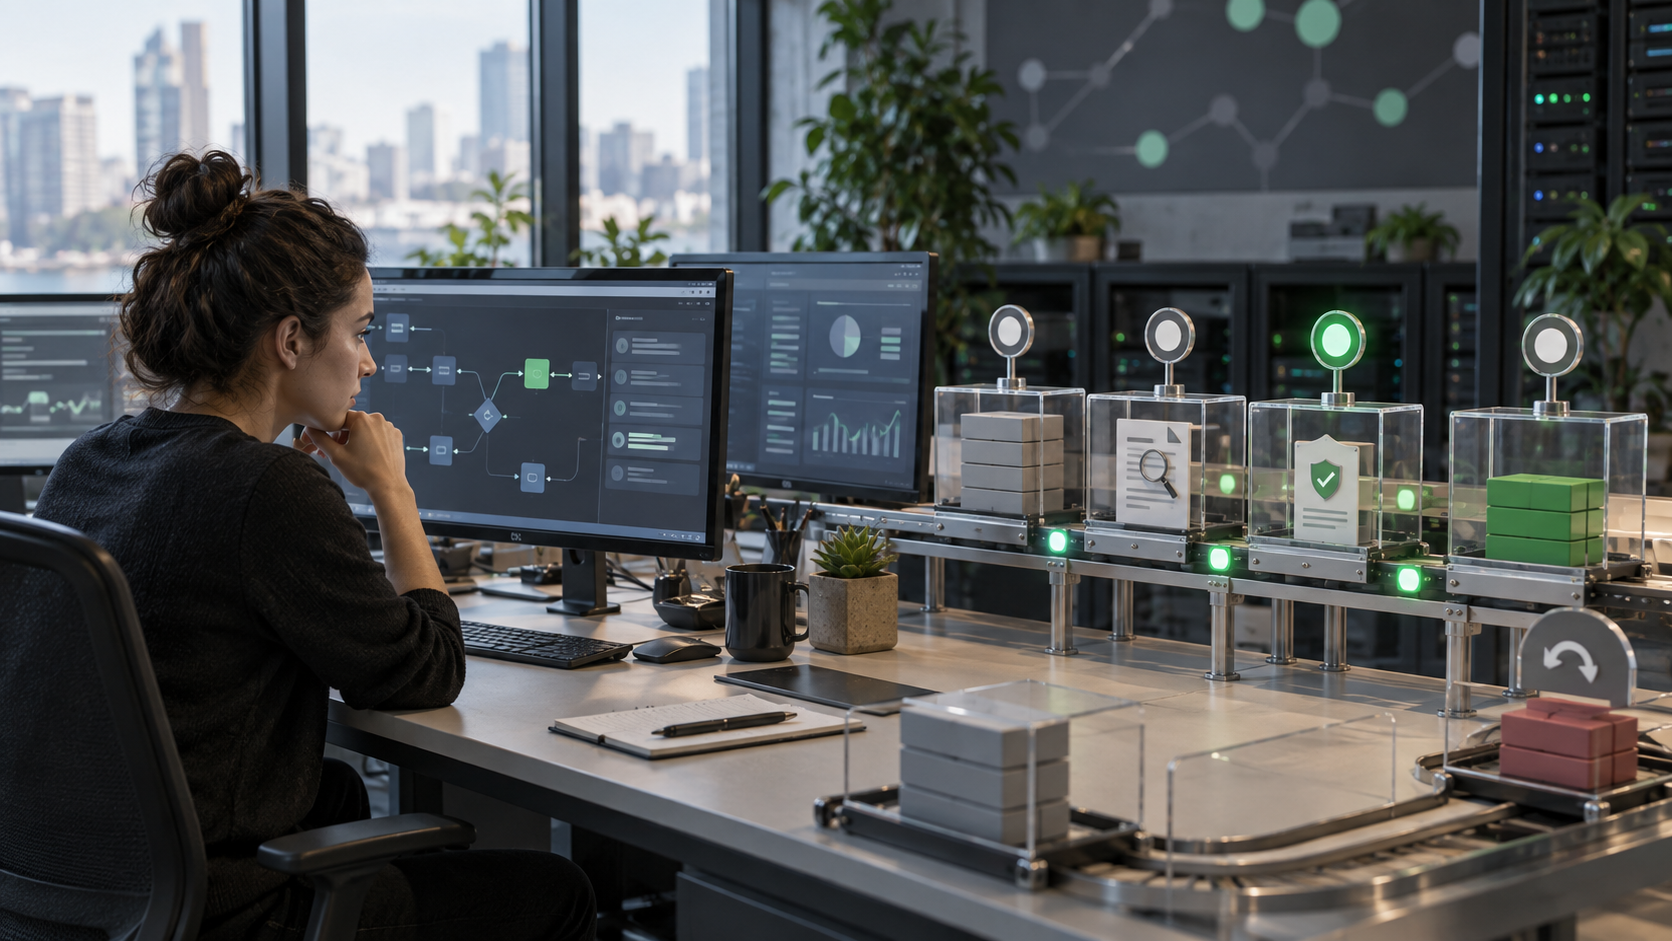
The practical answer is reversibility. Before giving an agent broader authority, make its actions inspectable, scoped, and recoverable. A system that can undo a mistake safely is more useful than one that completes a longer demo while leaving operators to reconstruct what happened.
Autonomy is not a single dial
Agent discussions often collapse several design choices into one word. A system may independently plan work but require approval before execution. It may execute freely in a sandbox but have no production credentials. It may write to production while being limited to a small set of reversible operations. These are different authority profiles, not points on a simple ladder.
Anthropic's guide to building effective agents distinguishes structured workflows from more open-ended agents and argues for matching complexity to the task. That is a useful starting point because many business processes do not need an unconstrained planner. They need a model inside a well-designed state machine.
Reversibility adds another axis to that decision. An agent can be allowed to act more freely where operations are cheap to undo. Drafting a pull request is safer than merging it. Preparing an email is safer than sending it. Proposing database mutations inside a transaction is safer than applying them directly. The distinction is not whether a human clicked a button; it is whether the system preserved a reliable path back.
Design the action surface, not just the prompt
A careful system exposes tools at the level of business intent. Instead of giving an agent arbitrary database access, provide an operation such as “propose customer-address change.” That operation can validate fields, record the previous state, enforce tenant boundaries, request approval when risk is high, and emit an audit event. The model supplies judgment; deterministic software controls the blast radius.
Several patterns make that arrangement work:
- Stage before commit. Let the agent assemble a change set, then validate and apply it as a separate operation.
- Prefer append-only records. New events are easier to inspect and compensate for than silent overwrites.
- Issue narrow, temporary credentials. Authority should expire and should cover only the current task.
- Use compensating actions. When literal rollback is impossible, define the operational repair in advance.
- Escalate on consequence. Approval thresholds should follow potential harm, not how uncertain the model sounds.
The final principle deserves emphasis. Models are not consistently calibrated narrators of their own uncertainty. A confident sentence can precede a bad action, while a cautious one may be correct. A payment, public communication, or destructive infrastructure change should receive scrutiny because of what it can do.
Evaluation should test recovery
Most agent evaluations focus on task completion. That creates systems optimized to reach an end state, sometimes by brittle or surprising routes. OpenAI's documentation on working with evals supports a more disciplined practice of defining and testing the behavior an application actually needs. For consequential agents, recovery behavior belongs in that definition.
Inject a duplicate request and see whether the agent performs an action twice. Revoke a credential halfway through a task. Change the underlying record after the plan is created. Return a partial tool failure. Ask the operator to undo the last three actions. Then measure whether the system can identify what happened, distinguish completed work from proposed work, and restore a valid state.
This changes observability requirements. A transcript is not enough. Teams need durable action identifiers, structured inputs and outputs, state snapshots or event histories, approval records, and links between a model's proposal and the operation that executed it. Otherwise, “undo” becomes an archaeological exercise conducted across logs.
Trust grows from controlled consequences
Human approval remains useful, but it should not become a ritual that transfers liability to a tired operator. If every low-risk step demands a click, people will approve mechanically. If the interface shows an intelligible diff, highlights irreversible consequences, and groups safe actions, review becomes meaningful.
The goal is graduated authority. Start the agent in observation mode. Let it draft changes. Allow automatic execution for reversible, low-impact operations once evaluations are strong. Expand permissions only when logs show that both normal execution and recovery are reliable. This resembles how effective teams grant access to new engineers: responsibility grows with demonstrated judgment and with the quality of the surrounding controls.
There will always be operations that cannot truly be reversed. A leaked secret cannot be unlearned; a public message cannot be made unseen. Those boundaries should be explicit and rare, protected by stronger review or excluded from the agent's tools entirely.
The most credible agent will not be the one that never pauses. It will be the one an organization can understand when it succeeds, contain when it fails, and trust with more responsibility over time. Before adding another planning loop, build the reverse gear.
Advertisement


