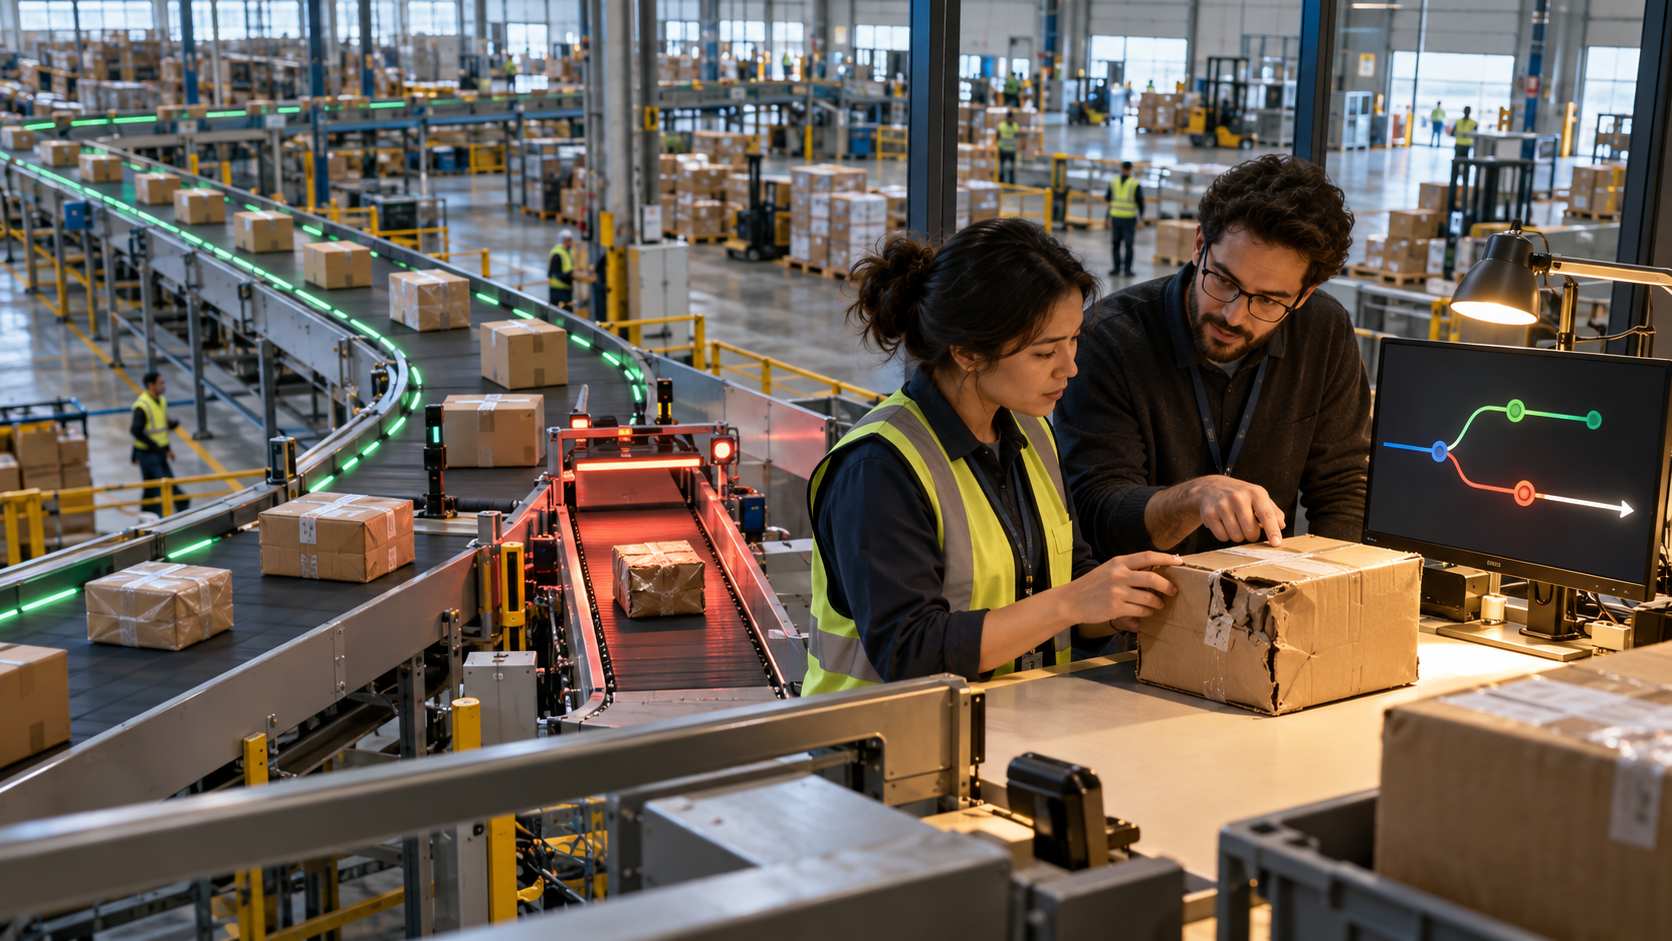
A familiar enterprise AI proposal begins with a percentage: automate most tickets, review most documents, resolve most requests. The number creates an illusion of completeness. What determines whether the system survives contact with operations, however, is the remaining slice—the ambiguous, consequential, malformed, adversarial, or simply unprecedented cases that do not fit the automated path.
Teams often label those cases “human in the loop” and move on. That phrase hides the hard design work. Which human? Shown what evidence? At what point? With how much time? Can that person reverse an external action? Does the case return to automation afterward, and does the system remember the correction? Without answers, human review is not a safety mechanism. It is a queue where accountability goes to disappear.
The exception lane is part of the product
Traditional workflow software makes branching explicit. A payment above a threshold requires approval; an address mismatch creates a hold; an unavailable inventory item triggers substitution. Language-model systems tempt builders to replace such visible branches with a broad instruction to “use judgment.” That can make the demo fluid while making the operation illegible.
A production workflow needs named states even when the model supplies flexible reasoning between them. Work may be unclassified, in progress, awaiting evidence, awaiting approval, completed, or failed. External actions should carry identifiers and be safe to retry. The interface should distinguish a proposed action from one already executed. These are not relics of pre-AI engineering. They are how probabilistic behavior becomes governable.
Anthropic’s guidance on building effective agents draws a useful distinction between structured workflows and systems that dynamically direct their own processes. The practical takeaway is to earn complexity. If a fixed sequence with a few model-assisted decisions can solve the task, an open-ended agent may add failure modes without adding customer value.
Confidence is not the same as risk
Many systems route cases to people when model confidence falls below a threshold. That is necessary in some settings and insufficient in most. A highly confident answer can still authorize a costly refund, disclose private information, or modify the wrong account. A low-confidence classification may be harmless if it merely changes the order of an internal list.
Escalation should combine uncertainty with consequence and reversibility. Consider four questions: How unsure is the system? How costly is a wrong action? How easily can the action be undone? How quickly would anyone detect the error? A modestly uncertain recommendation that remains a draft may proceed. A seemingly certain instruction to transfer money deserves an independent control.
The NIST AI Risk Management Framework offers a broader vocabulary for mapping and managing AI risk. Teams can make that concrete by attaching risk classes to tools and transitions. Searching an internal knowledge base is not equivalent to emailing a customer. Drafting a database update is not equivalent to committing it. Permissions should reflect that gradient.
Give reviewers a decision, not a transcript
Human review fails when the reviewer must reconstruct the entire machine process from a wall of logs. An effective handoff presents the original request, relevant source evidence, the system’s proposed action, the reason for escalation, and the deadline or consequence of delay. It should make uncertainty visible without forcing the person to decode token probabilities.
The reviewer also needs meaningful controls. “Approve” and “reject” may be too coarse. Useful options might include correcting a field, requesting more evidence, narrowing the action, returning the case to a specific step, or escalating to a domain specialist. Those choices generate structured feedback that can improve prompts, policies, retrieval, and future evaluations.
Operational disciplines developed long before generative AI remain relevant. Google’s freely available Site Reliability Engineering book emphasizes observability, incident response, and learning from failure. AI workflows need the same seriousness, extended to semantic decisions. Operators should be able to answer not only whether a service call failed, but why the system believed an action was appropriate and which evidence influenced it.
Automation rate is a misleading north star
If a team is rewarded mainly for reducing human touches, it will automate cases that should remain supervised and make escalation inconvenient. The healthier metric is safe resolution cost: the combined expense of machine execution, human attention, delay, correction, and undetected error. Sometimes adding a fast human check lowers that total. Sometimes improving the reviewer interface delivers more value than changing the model.
This perspective also changes rollout strategy. Start with the exception lane and run the system in observation mode. Let it propose classifications and actions while people remain authoritative. Compare disagreements, identify missing evidence, and measure reviewer effort. Then automate low-consequence, reversible transitions first. Expand only when the operation can detect and recover from mistakes.
The goal is not to preserve human involvement for sentimental reasons. It is to allocate judgment intelligently. Machines are excellent at processing volume, applying repeatable transformations, and gathering context. People remain valuable when goals conflict, precedent is thin, or consequences extend beyond what the system can represent.
A mature AI workflow does not pretend exceptions will vanish as models improve. Better models move the boundary; they do not abolish it. New capabilities also invite new responsibilities and more consequential actions. The durable system is therefore not the one with the fewest handoffs. It is the one whose handoffs are timely, informed, reversible, and capable of teaching the rest of the operation.
Advertisement


