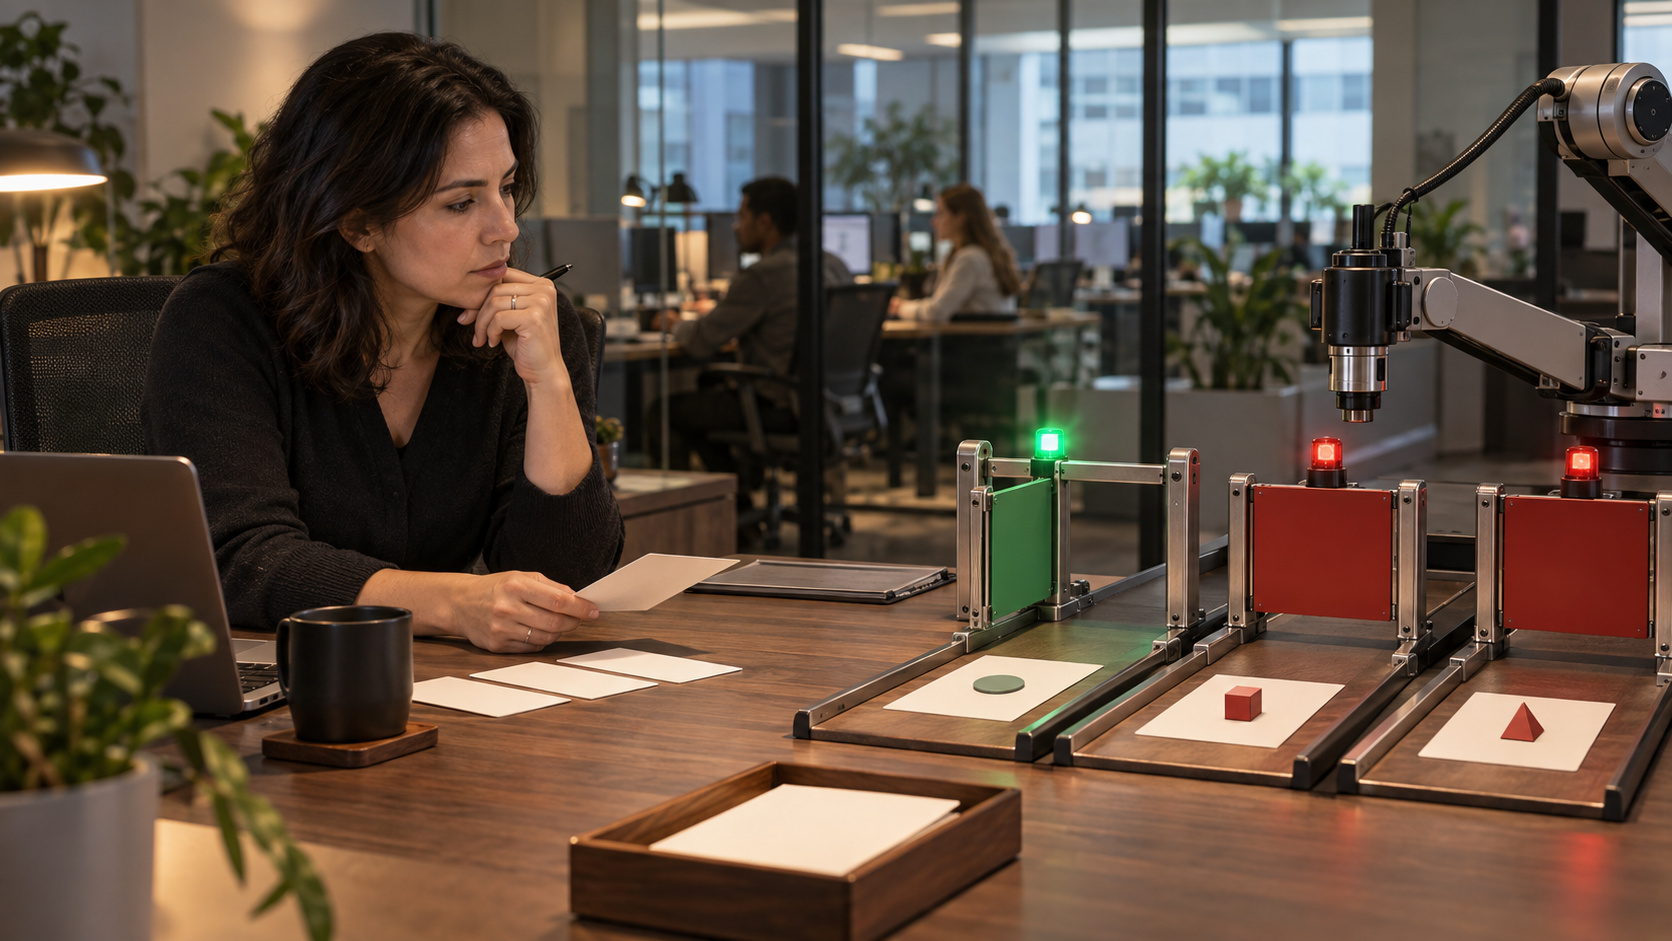
Most demonstrations of AI agents focus on motion: the cursor clicks, tabs open, code changes, messages fly. Activity is persuasive on video. In production, however, the quality that determines whether an agent is useful is not motion but authority.
Can it read the customer record? Can it edit it? Can it issue a refund, send an email, merge a branch, or sign a contract? Who approved those capabilities, for how long, and under what conditions? An agent becomes operationally meaningful at the moment its output changes shared state. That moment should be the center of product design.
Too many systems bolt permissions onto an agent after the workflow has been built. This reverses the proper dependency. The permission model should shape the tools, the interface, the evaluation plan, and even the tasks the agent is offered.
Replace the autonomy slider with an authority map
“Human in the loop” is too vague to be a design specification. A person who clicks approve on dozens of opaque actions is technically present but functionally absent. Conversely, an agent may operate for hours without intervention while remaining safe because its actions are constrained, observable, and reversible.
A better model separates authority along several dimensions:
Resource: Which accounts, repositories, documents, or customers can the agent access?
Operation: May it read, draft, edit, publish, transfer, delete, or execute?
Magnitude: Is the action limited by money, audience size, data volume, or production impact?
Duration: Is authority granted once, for a session, or indefinitely?
Reversibility: Can the effect be rolled back, and is that rollback actually tested?
This authority map is more useful than labeling an agent “level three autonomous.” It describes the real blast radius. Reading ten invoices and drafting a summary may require little supervision. Sending that summary externally, changing payment details, or deleting the source records are categorically different operations even if they appear in the same workflow.
Tool design is policy design
Agent builders often treat tools as thin wrappers around existing APIs. That gives the model whatever power the underlying service exposes, frequently through broad operations with ambiguous parameters. It is convenient engineering and poor governance.
Tools should instead encode policy. A narrowly defined draft refund recommendation tool is safer than a generic function that can update any field on an order. A file-editing tool can require an explicit path, reject writes outside a workspace, and return a preview before committing. An email tool can distinguish drafting from sending and limit recipients by domain.
Anthropic’s guide to building effective agents emphasizes simple, composable patterns and carefully designed tool interfaces. That advice has a security consequence: smaller, clearer tools make authority understandable to both the model and the people reviewing its behavior. Complexity does not merely create maintenance cost; it obscures where consequential power resides.
Approval should be a meaningful decision
An approval screen should tell a reviewer what will change, why the agent proposes it, what evidence it used, and whether the action can be undone. The default artifact is not a transcript of the model’s internal monologue. It is a concise change set.
For code, that may be a diff plus test results. For a CRM, it may be the exact records and fields to update. For procurement, it may be vendor, amount, budget owner, and policy checks. Approval requests should be grouped by shared intent rather than emitted one click at a time. Otherwise, supervision degrades into alert fatigue.
The interface should also support partial approval. A reviewer may accept the analysis but reject the external message, approve nine record updates but hold one exception, or authorize a lower spending limit. Binary accept-or-cancel controls force people to redo safe work or wave through risky work.
Untrusted content must not grant authority
Agents read web pages, emails, tickets, documents, and tool outputs. Any of those sources can contain instructions that conflict with the user’s goal. Prompt injection is therefore not just a model weakness; it is a confused-deputy problem in which untrusted content attempts to steer a system that holds valuable permissions.
Anthropic’s discussion of trustworthy agents in practice argues for layered defenses across the model, harness, tools, and operating environment. Product teams should take the architectural implication seriously: content being processed must never be treated as equivalent to authority granted by the user.
A purchase order can supply data about what to buy; it should not be able to expand the agent’s purchasing limit. A support ticket can describe an account problem; it should not authorize disclosure of another customer’s records. Every tool call should be evaluated against permissions that live outside the content stream the model is interpreting.
Reversibility is a product feature
Undo is often discussed as damage control. It is also an adoption mechanism. People delegate more confidently when they can inspect an action log, restore prior state, and understand what depended on the change.
True reversibility requires engineering work: versioned records, idempotent operations, compensating transactions, staged publication, and retained provenance. Some actions—sending sensitive data or transferring money—cannot be perfectly undone. The system should recognize that distinction and demand stronger confirmation before crossing the boundary.
The goal is not to keep agents permanently timid. It is to create a path by which they earn broader authority. Start with observation, progress to drafts, then reversible changes, and only later permit consequential execution where evidence supports it. Measure correction rates and near misses at every stage.
The best agent will not be the one that asks for the fewest approvals. It will be the one that asks at the right boundaries, presents decisions clearly, and never confuses access with permission. Autonomy is not a feature teams switch on. It is trust accumulated through well-designed constraints.
Advertisement


